Restaurants & Hospitality
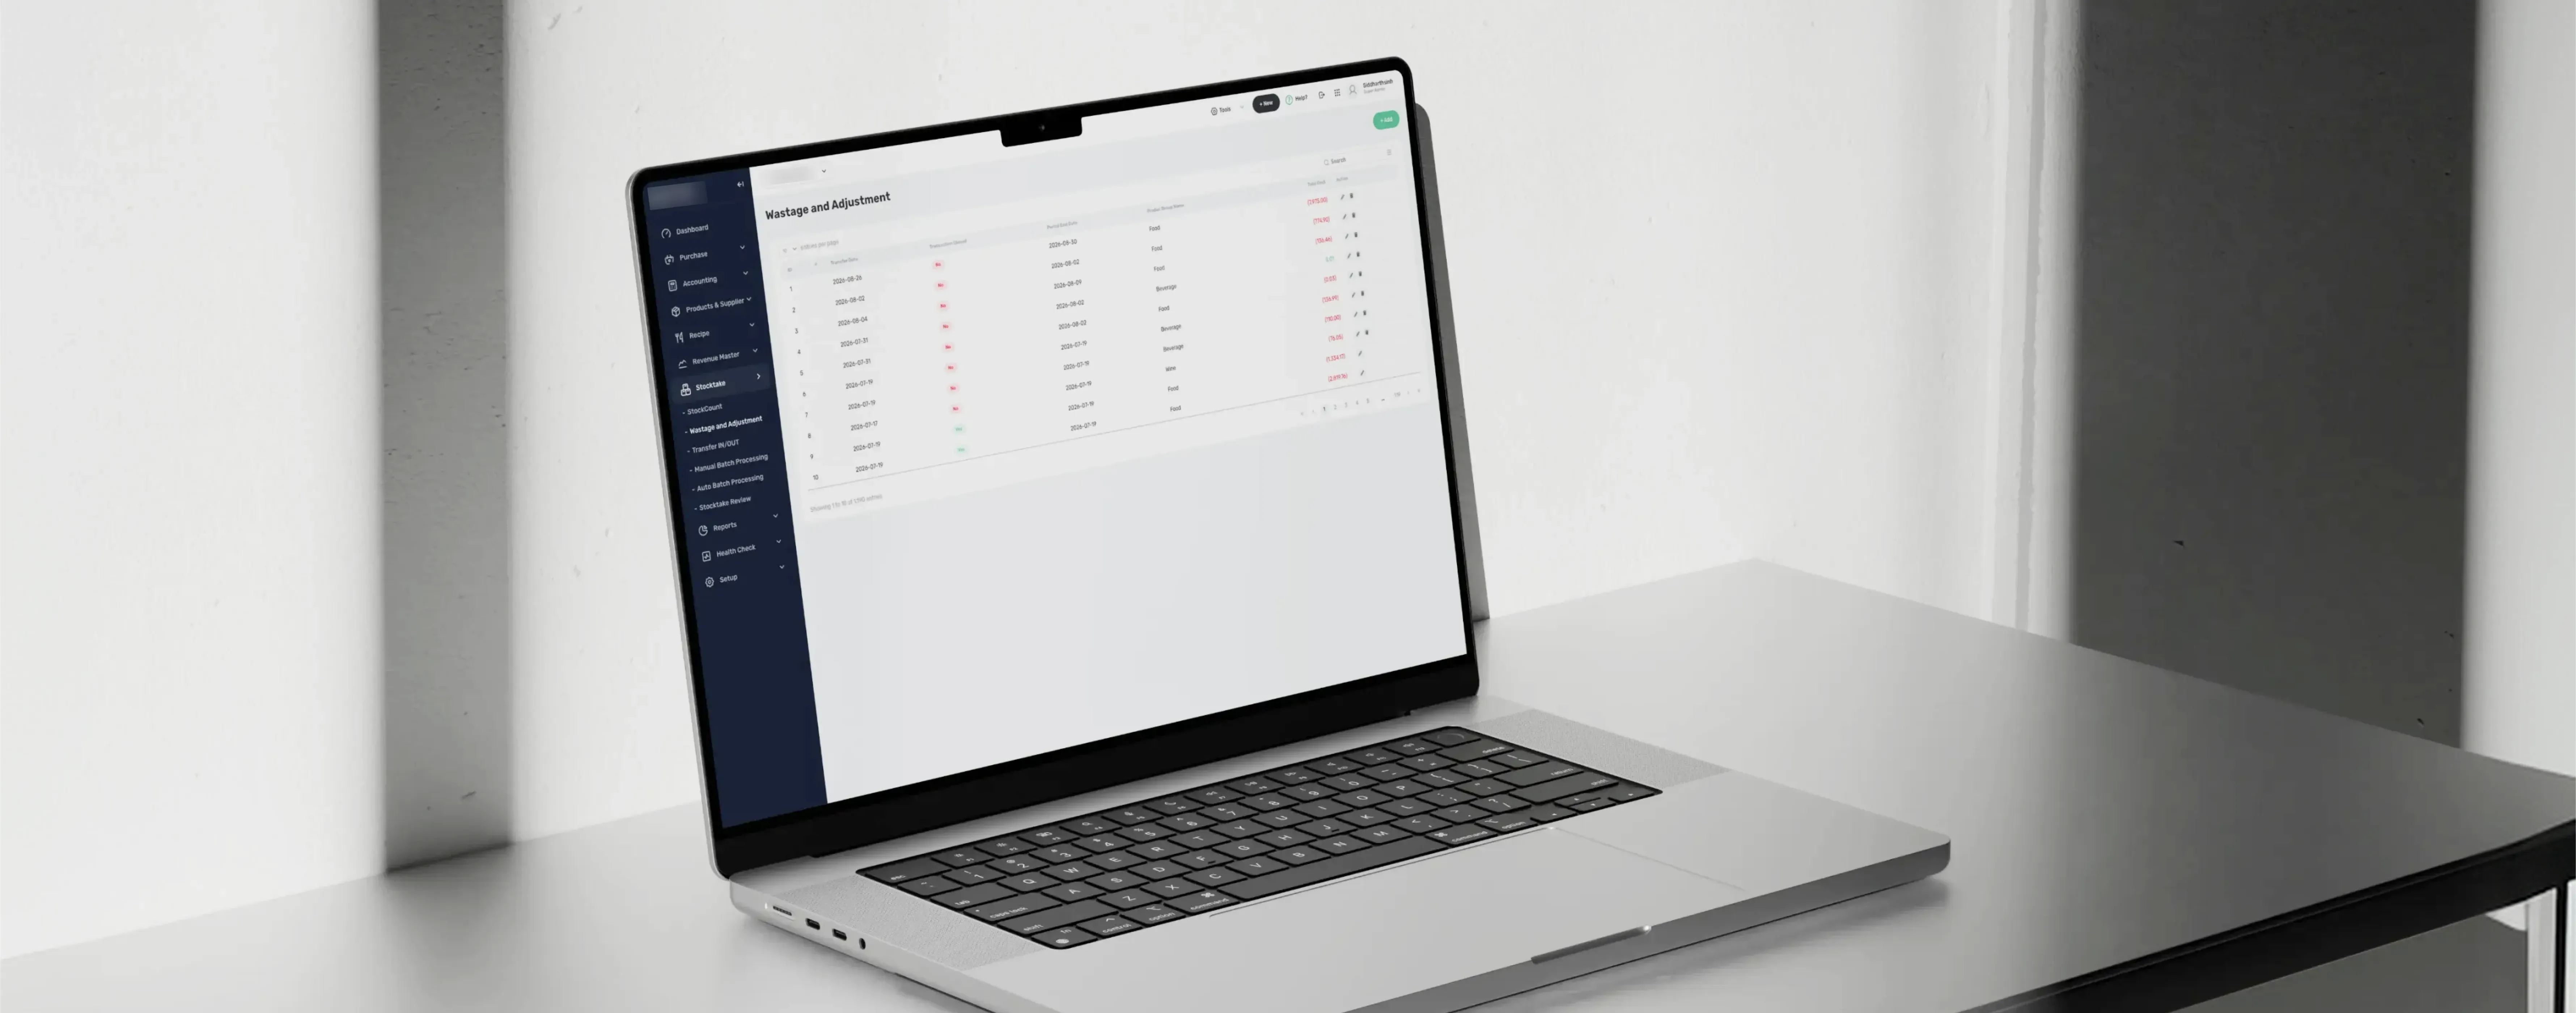
Restaurant Wastage & Stock Transfer Control
Discover how restaurant wastage and stock transfer control help track inventory movement, reduce product waste, and improve stock visibility across locations.
View Case Study
From cloud data warehouse architecture and data modelling to Snowflake migration, query performance tuning, and BI layer design — Cinovic engineers data warehouses that your analysts trust, your business acts on, and your engineers can maintain.
We partner with growing businesses and enterprise data teams who need a warehouse partner that understands schema design, query optimisation, data modelling, cost governance, and the full journey from raw data to trusted BI — not just infrastructure provisioning.
We don't just provision a Snowflake account — we design the schema, model the data, build the pipelines, optimise the queries, govern the costs, and connect everything to your BI layer — so your warehouse delivers value from day one.
Real data warehouse projects. Real performance outcomes. See how Cinovic has helped data teams move from slow, unreliable reporting to fast, trusted, scalable analytics platforms.
Discover how restaurant wastage and stock transfer control help track inventory movement, reduce product waste, and improve stock visibility across locations.
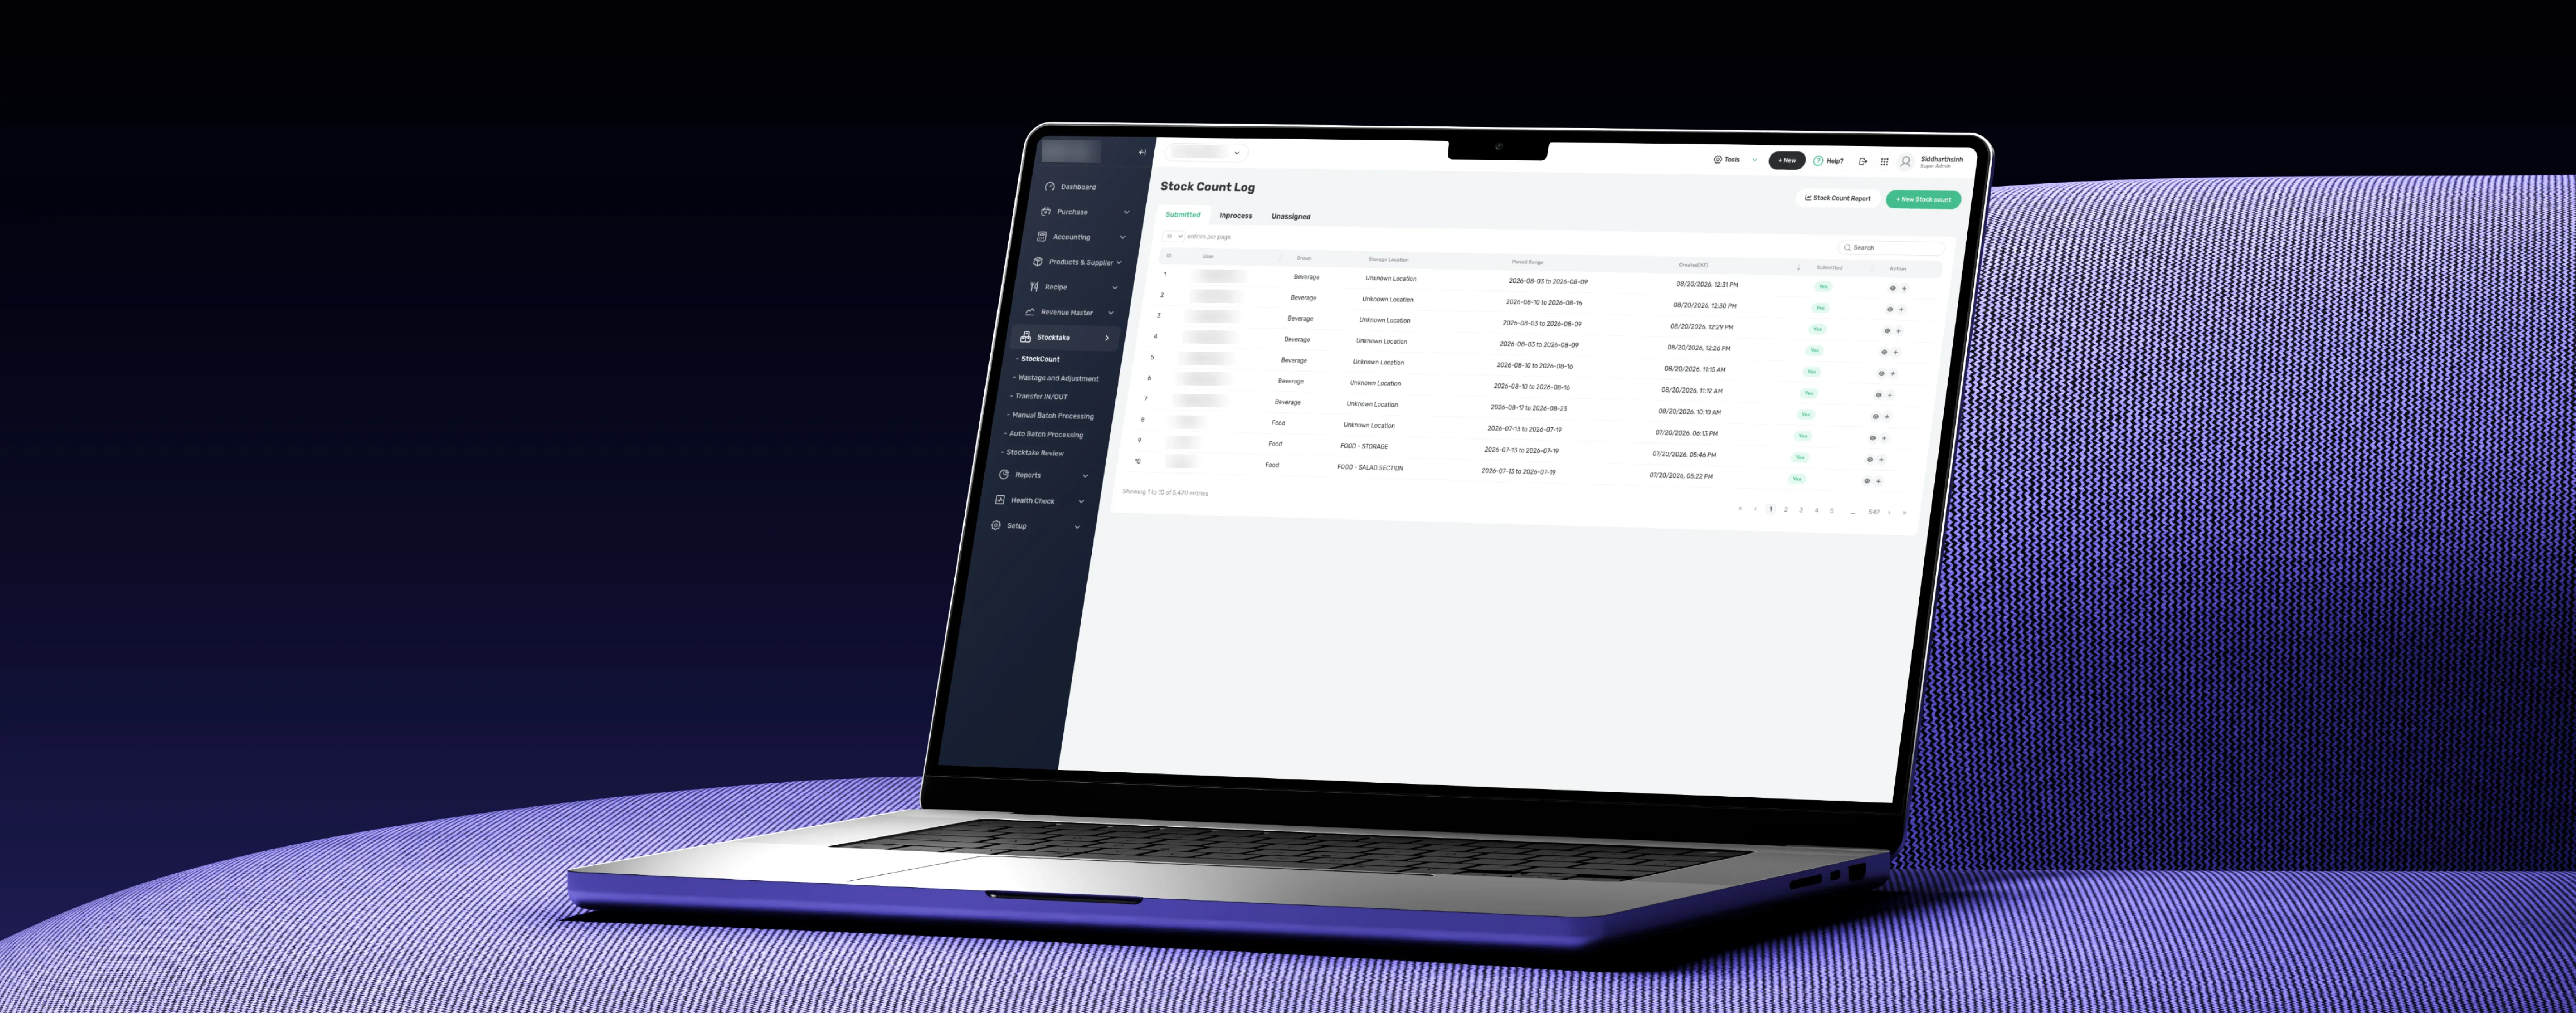
Discover how restaurant inventory control solutions help manage products, improve stock visibility, reduce manual work, and support efficient operations.
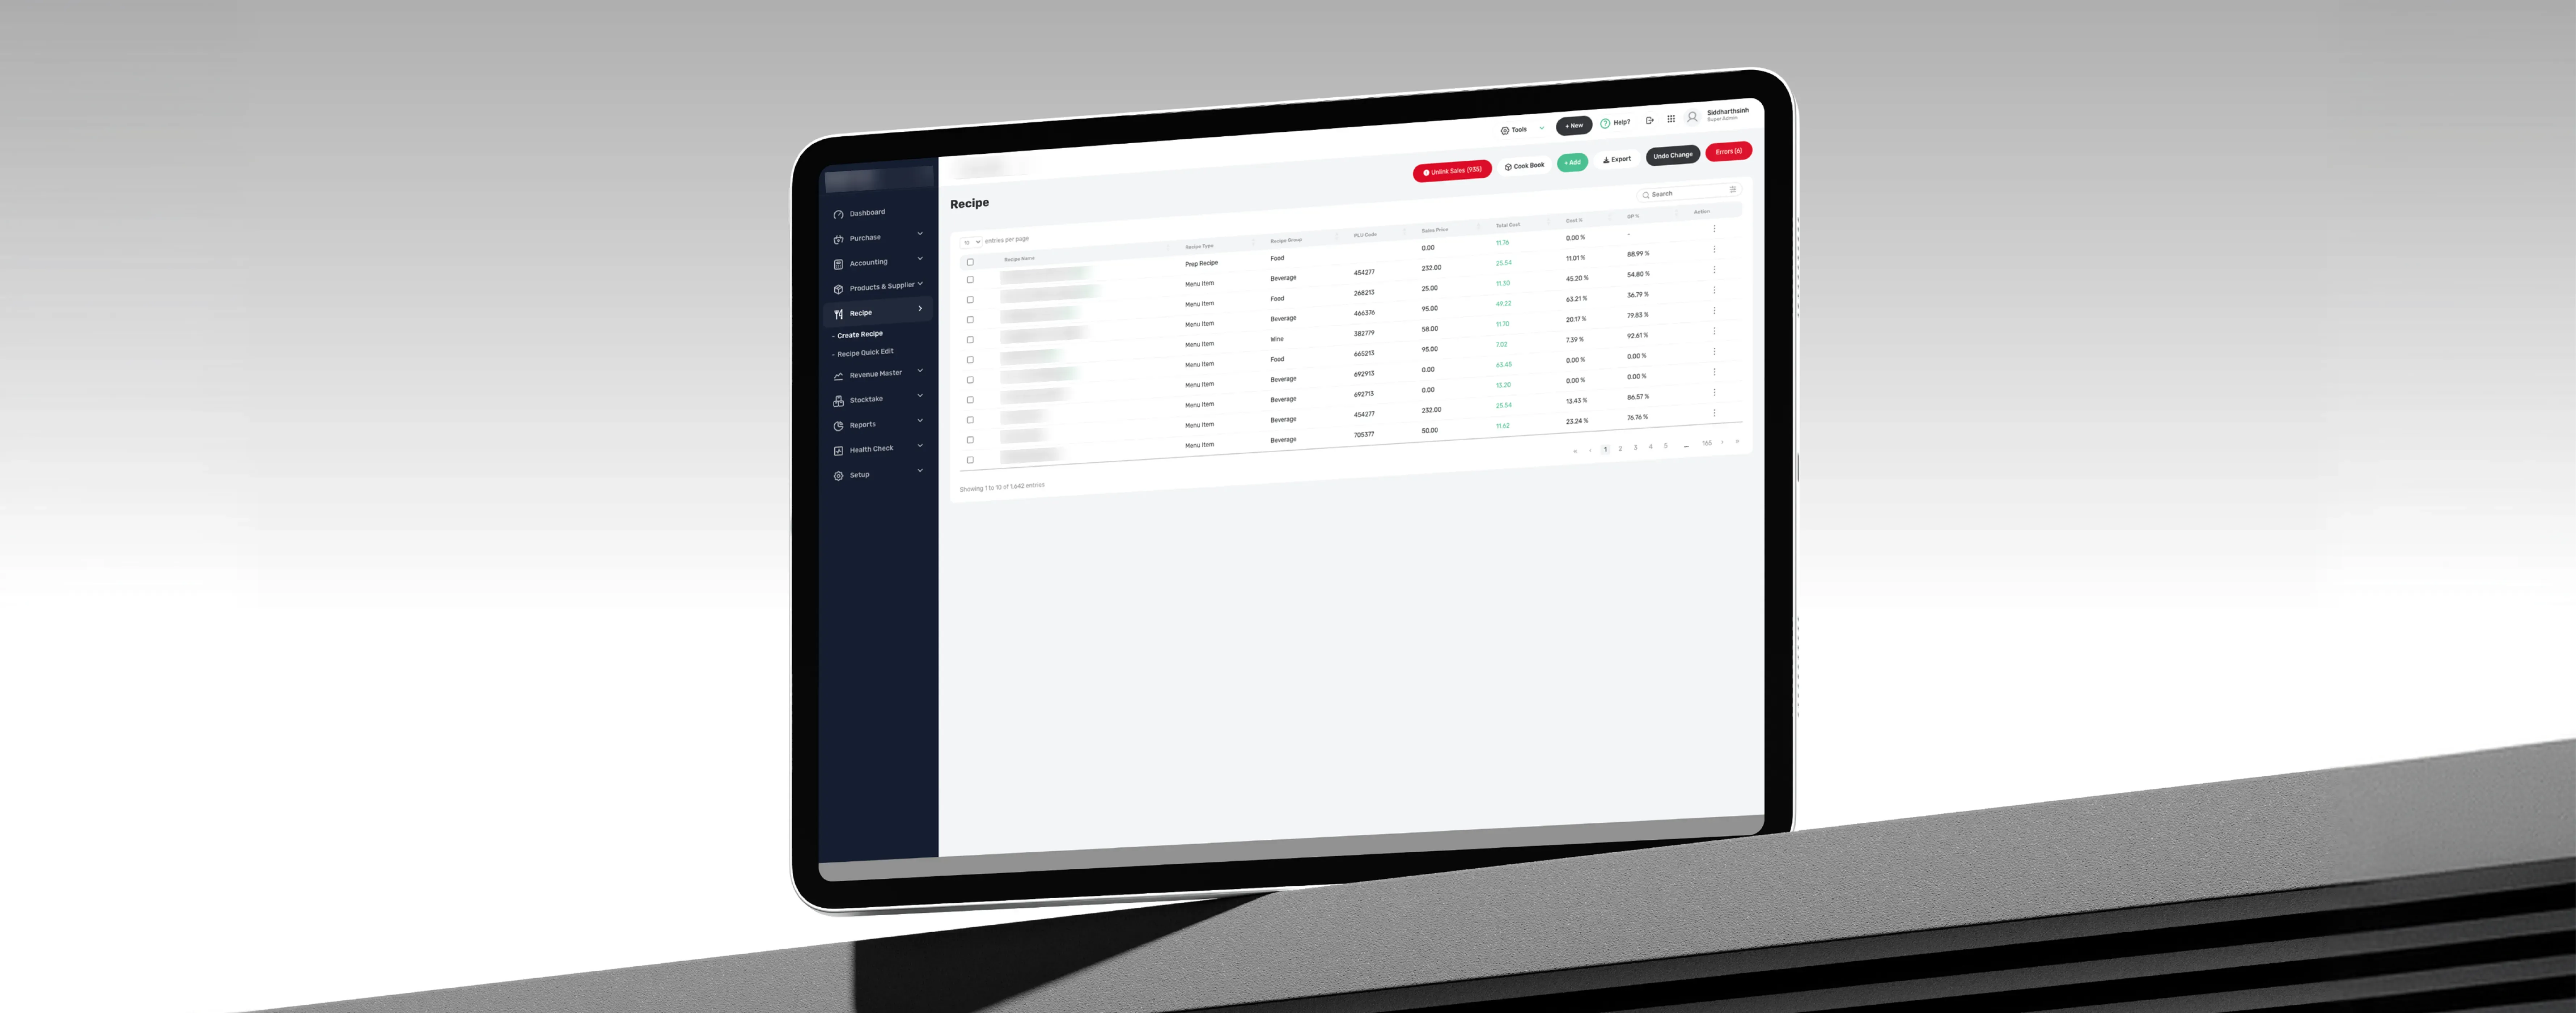
Discover how recipe and menu control solutions help kitchens manage recipes, standardize menus, and maintain consistent food operations across locations.
From cloud data warehouse architecture and data modelling to warehouse migration, performance tuning, cost optimisation, and BI layer connectivity — we cover the full data warehouse lifecycle.
Design your cloud data warehouse from the ground up — platform selection (Snowflake vs BigQuery vs Redshift vs Synapse), logical and physical schema design, modelling strategy selection (Kimball, Data Vault 2.0, or One Big Table), zone architecture, and capacity planning aligned to your query SLAs and budget.
Build structured, maintainable, and analytically powerful data models — Kimball star schemas and conformed dimensions, Data Vault 2.0 hubs, links, and satellites, One Big Table (OBT) models for high-throughput queries, and semantic layer definitions in dbt or Looker LookML that expose consistent business metrics.
Migrate from on-premise data warehouses (SQL Server, Oracle, Teradata, IBM Netezza) or legacy cloud platforms to modern cloud warehouses — with full data migration, ETL/ELT re-engineering, schema transformation, historical data validation, and zero-disruption cutover planning.
Diagnose and fix slow, expensive data warehouse queries — query profiling and execution plan analysis, clustering key and partition redesign, materialised view strategy, warehouse auto-scaling configuration, caching layer optimisation, and long-running query elimination.
Implement warehouse cost governance frameworks — resource monitors and credit alerts (Snowflake), slot commitment analysis (BigQuery), reserved instance planning (Redshift), cost tagging by team/project, query cost attribution, and automated idle warehouse suspension policies.
Connect your data warehouse to Looker, Power BI, Tableau, Metabase, or Superset — designing optimised semantic layers, BI-specific data marts, pre-aggregated tables, and row-level security policies so every analyst gets fast, governed, self-serve access to trusted data.
Design your cloud data warehouse from the ground up — platform selection (Snowflake vs BigQuery vs Redshift vs Synapse), logical and physical schema design, modelling strategy selection (Kimball, Data Vault 2.0, or One Big Table), zone architecture, and capacity planning aligned to your query SLAs and budget.
Build structured, maintainable, and analytically powerful data models — Kimball star schemas and conformed dimensions, Data Vault 2.0 hubs, links, and satellites, One Big Table (OBT) models for high-throughput queries, and semantic layer definitions in dbt or Looker LookML that expose consistent business metrics.
Migrate from on-premise data warehouses (SQL Server, Oracle, Teradata, IBM Netezza) or legacy cloud platforms to modern cloud warehouses — with full data migration, ETL/ELT re-engineering, schema transformation, historical data validation, and zero-disruption cutover planning.
Diagnose and fix slow, expensive data warehouse queries — query profiling and execution plan analysis, clustering key and partition redesign, materialised view strategy, warehouse auto-scaling configuration, caching layer optimisation, and long-running query elimination.
Implement warehouse cost governance frameworks — resource monitors and credit alerts (Snowflake), slot commitment analysis (BigQuery), reserved instance planning (Redshift), cost tagging by team/project, query cost attribution, and automated idle warehouse suspension policies.
Connect your data warehouse to Looker, Power BI, Tableau, Metabase, or Superset — designing optimised semantic layers, BI-specific data marts, pre-aggregated tables, and row-level security policies so every analyst gets fast, governed, self-serve access to trusted data.
We combine data architecture expertise, cloud infrastructure depth, and analytics engineering discipline to build warehouses that analysts love, engineers trust, and executives make decisions from.
Design structured multi-layer warehouse architectures — Raw/Bronze ingestion zones, Cleansed/Silver transformation layers, and Curated/Gold analytics marts — ensuring clean separation of concerns, easier debugging, and reliable data lineage from source to dashboard.
Extend your data warehouse beyond batch loads — implementing streaming ingestion with Kafka, Kinesis, or Pub/Sub, micro-batch pipelines with Spark Structured Streaming, change data capture (CDC) using Debezium or Fivetran CDC, and near-real-time materialised views for operational dashboards.
Design and implement secure data sharing architectures — Snowflake Secure Data Sharing and Data Marketplace listings, BigQuery Analytics Hub datasets, cross-account data access policies, and governed external data sharing for partners, subsidiaries, and customers without data duplication.
Implement automated warehouse quality frameworks — dbt tests for row counts, uniqueness, referential integrity, and accepted value ranges, Great Expectations for source data profiling, column-level lineage tracking with OpenLineage or DataHub, and data freshness SLA monitoring with alerting pipelines.
Stay ahead with practical architecture guides, platform comparisons, modelling deep-dives, and case studies on Snowflake, BigQuery, Redshift, data modelling strategies, warehouse cost optimisation, and self-serve analytics.
Discover how to prepare your ecommerce store for agentic AI, from AI-powered shopping experiences to automation, personalization, and smarter commerce.
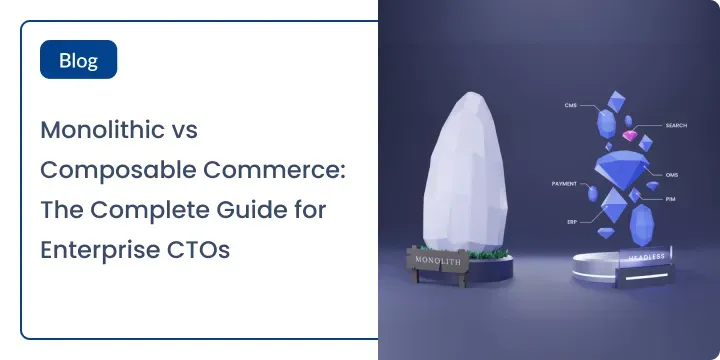
80% of enterprises are moving toward composable commerce. Compare monolithic vs. composable architecture and find the right fit with Cinovic’s free architecture assessment.
US social commerce hits $109.4B in 2026. TikTok Shop converts at 4.7%, more than double Instagram. Discover how zero-click commerce works across TikTok, Instagram, Google, and what your ecommerce store needs to do now. Free audit from Cinovic.
Tell us about your current data setup, your reporting bottlenecks, and your analytics goals — and we'll give you an honest assessment, a platform recommendation, and a practical roadmap to a faster, cheaper, more trusted data warehouse.
Snowflake vs BigQuery vs Redshift — Which Should We Use?A2:Snowflake is the most flexible — platform-agnostic, runs on AWS/Azure/GCP, excels at data sharing, multi-cloud, and workload isolation with its virtual warehouse model. BigQuery is Google's serverless warehouse — ideal for GCP-native teams who want zero infrastructure management and pay-per-query pricing. Redshift suits AWS-native organisations with heavy S3 integration and existing EMR workloads. Azure Synapse is the natural choice for Microsoft ecosystem businesses. We help you evaluate all four against your specific workload, team, and budget.
Snowflake is the most flexible — platform-agnostic, runs on AWS/Azure/GCP, excels at data sharing, multi-cloud, and workload isolation with its virtual warehouse model. BigQuery is Google's serverless warehouse — ideal for GCP-native teams who want zero infrastructure management and pay-per-query pricing. Redshift suits AWS-native organisations with heavy S3 integration and existing EMR workloads. Azure Synapse is the natural choice for Microsoft ecosystem businesses. We help you evaluate all four against your specific workload, team, and budget.
Data modelling is the process of structuring how data is organised, related, and stored in your warehouse. Good modelling makes queries faster, reporting more consistent, and analytics easier to maintain. Poor modelling is the most common reason warehouses run slowly or produce conflicting numbers. We use Kimball dimensional modelling, Data Vault 2.0, or One Big Table approaches depending on your use case, query patterns, and analytics maturity.
Yes — data warehouse migration is one of our core specialisms. We migrate from on-premise warehouses, including SQL Server, Oracle, Teradata, Netezza, and IBM DB2, to modern cloud platforms like Snowflake, BigQuery, or Redshift. Our migration process covers full data transfer, schema redesign, ETL/ELT re-engineering, historical data validation, and zero-disruption cutover planning.
High warehouse bills are almost always caused by one of four issues: unoptimised queries scanning too much data, oversized warehouses running when they shouldn't, missing clustering keys or partitions forcing full table scans, or runaway pipelines triggering excess compute. We audit your usage, identify the top cost drivers, and implement resource monitors, query optimisation, clustering strategies, and auto-suspend policies — typically reducing warehouse spend by 30–50%.