Restaurant Product & Recipe Data Management Platform
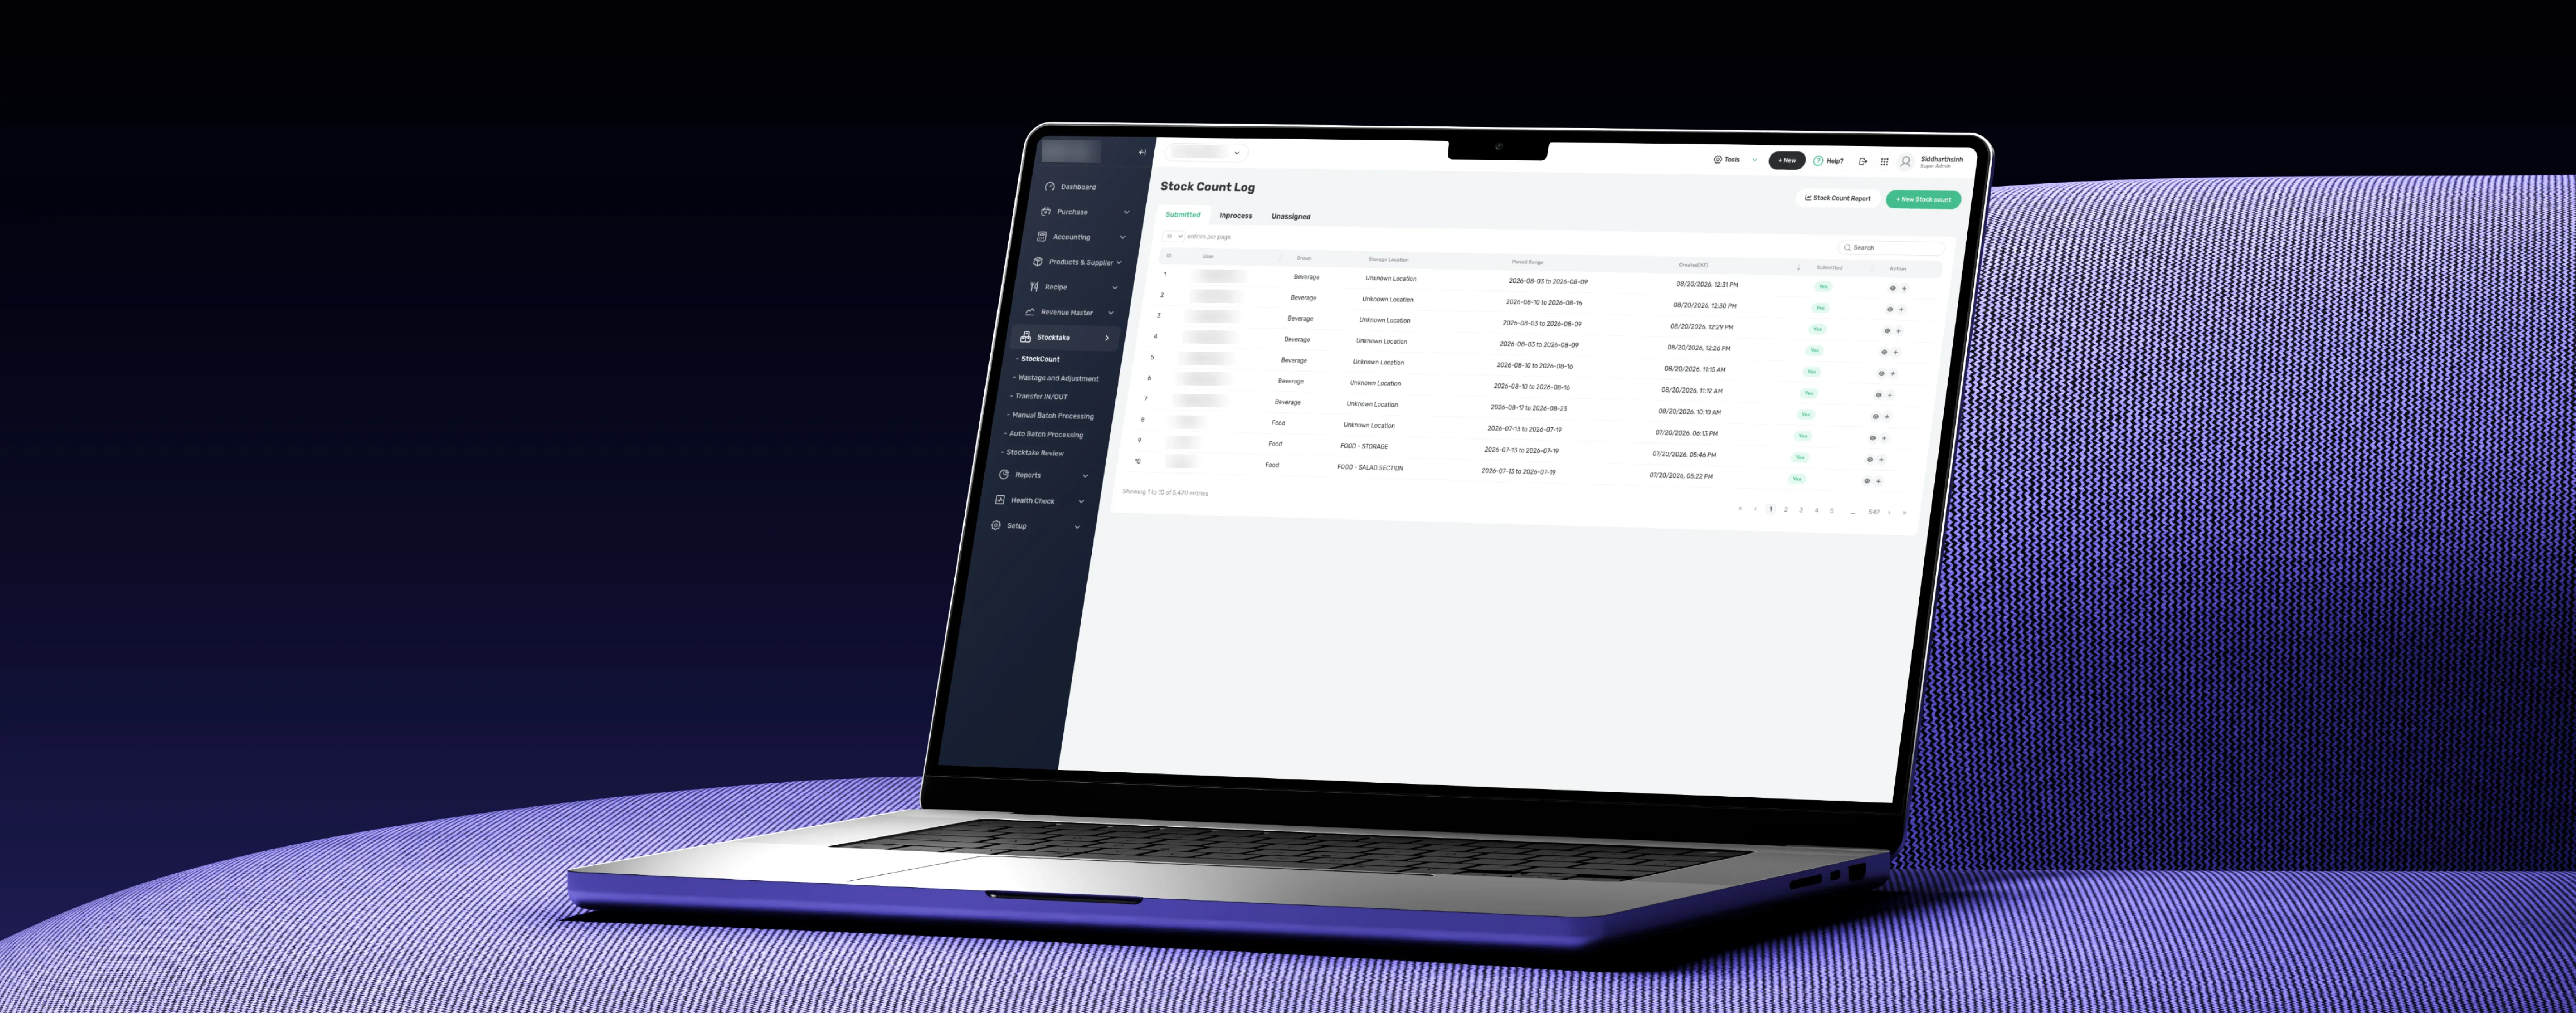
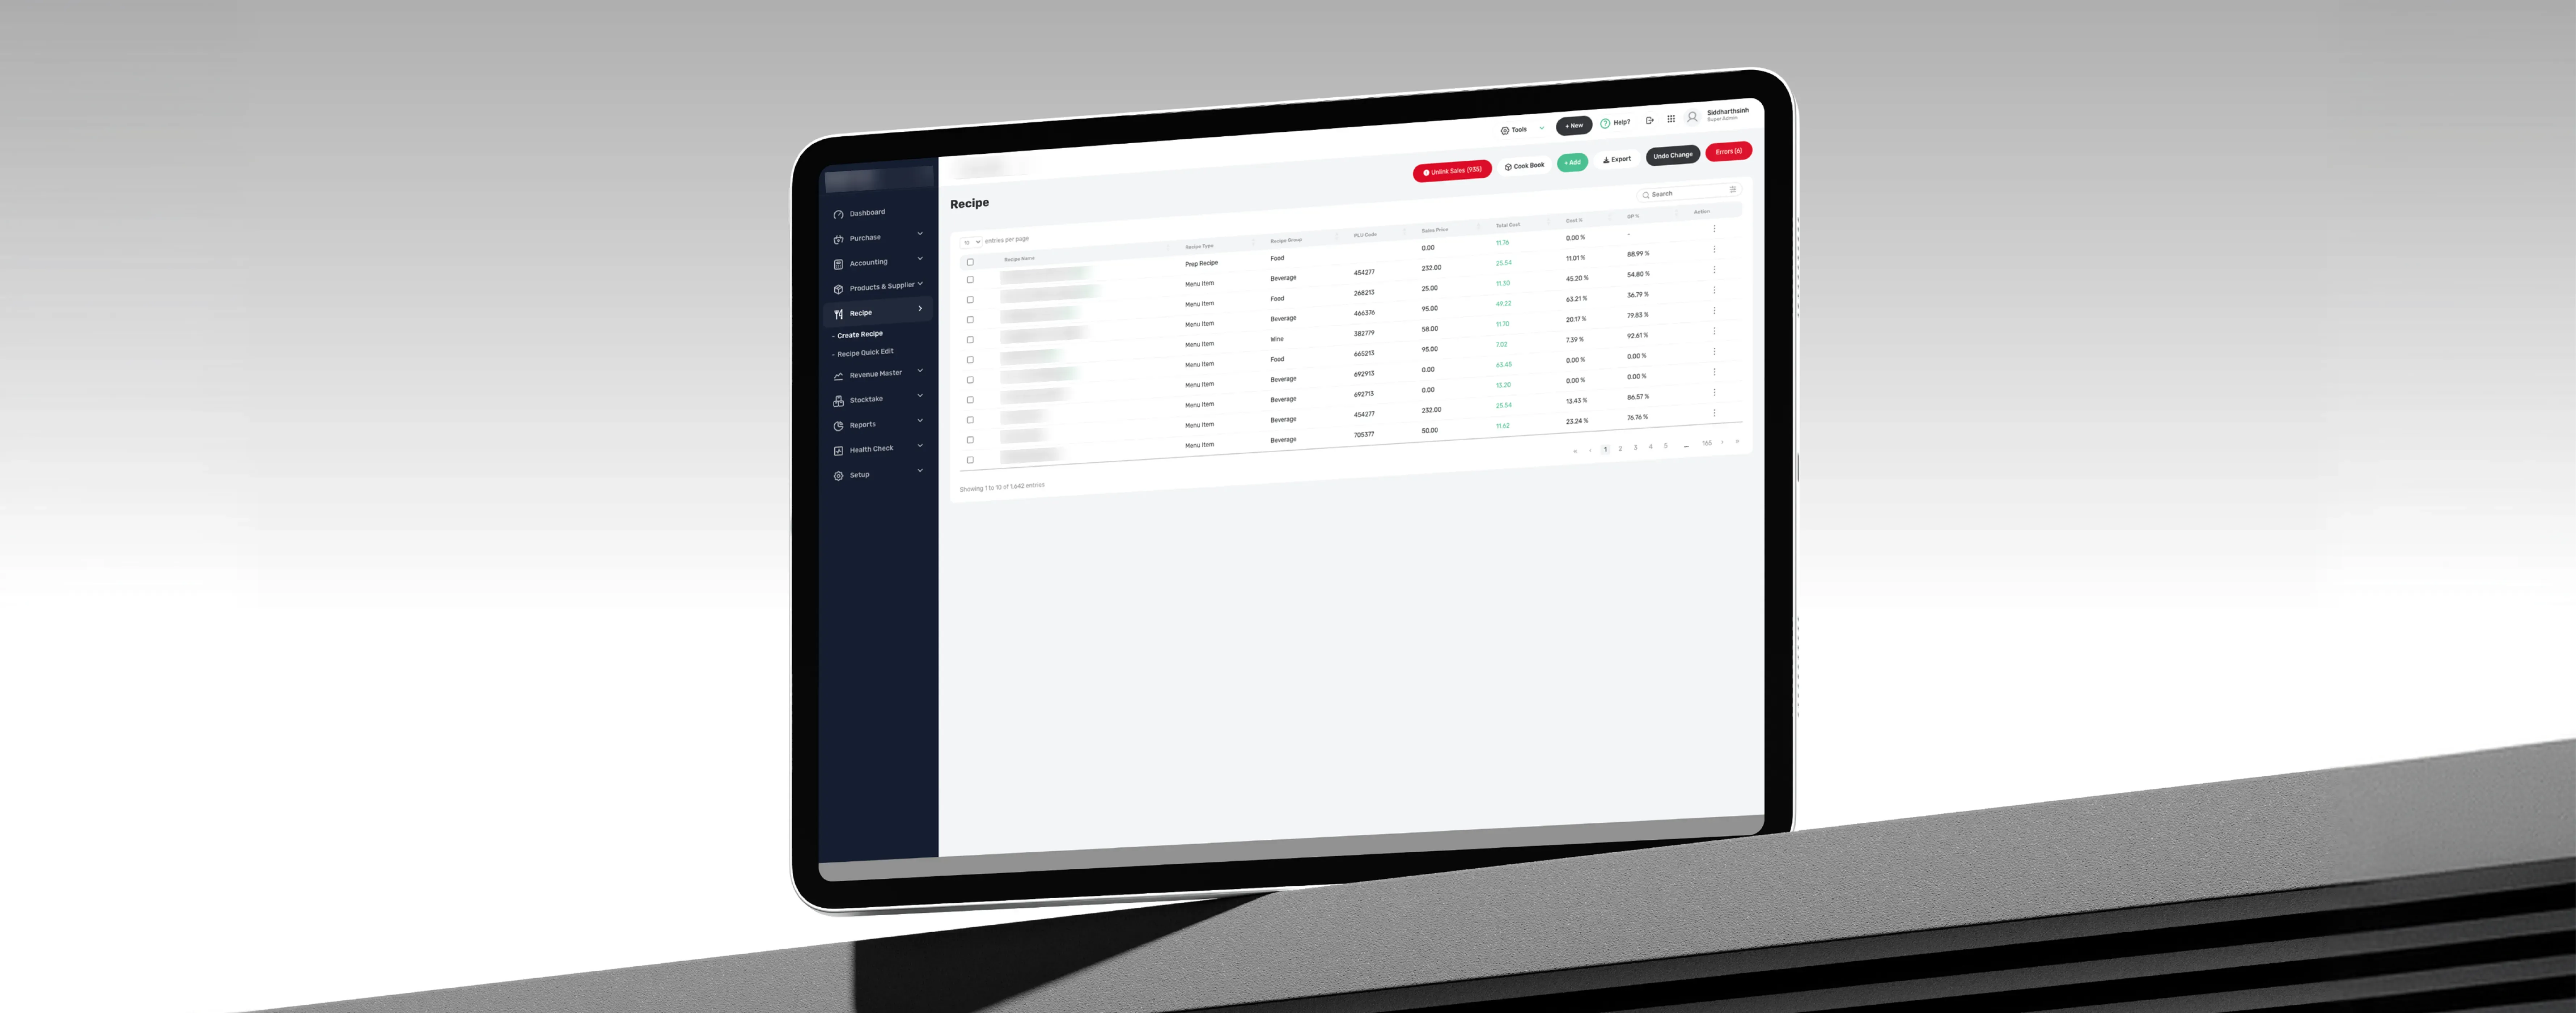
Explore a restaurant product and recipe data platform designed to centralize product information, manage recipes, and improve operational data consistency.
From CI/CD pipelines for ML to automated model monitoring, retraining, and cloud-native deployment, Cinovic engineers MLOps infrastructure that keeps your AI reliable, fast, and cost-efficient.

We partner with data-driven teams across industries to design, build, and operate MLOps infrastructure that keeps machine learning models accurate, monitored, and always production-ready.
We don't just build pipelines, we design battle-tested MLOps systems that eliminate model drift, accelerate deployment cycles, and give your team full observability over every model in production.
Real MLOps projects. Real production outcomes. See how Cinovic has helped teams deploy faster, monitor smarter, and scale ML systems with confidence.

Explore a restaurant product and recipe data platform designed to centralize product information, manage recipes, and improve operational data consistency.

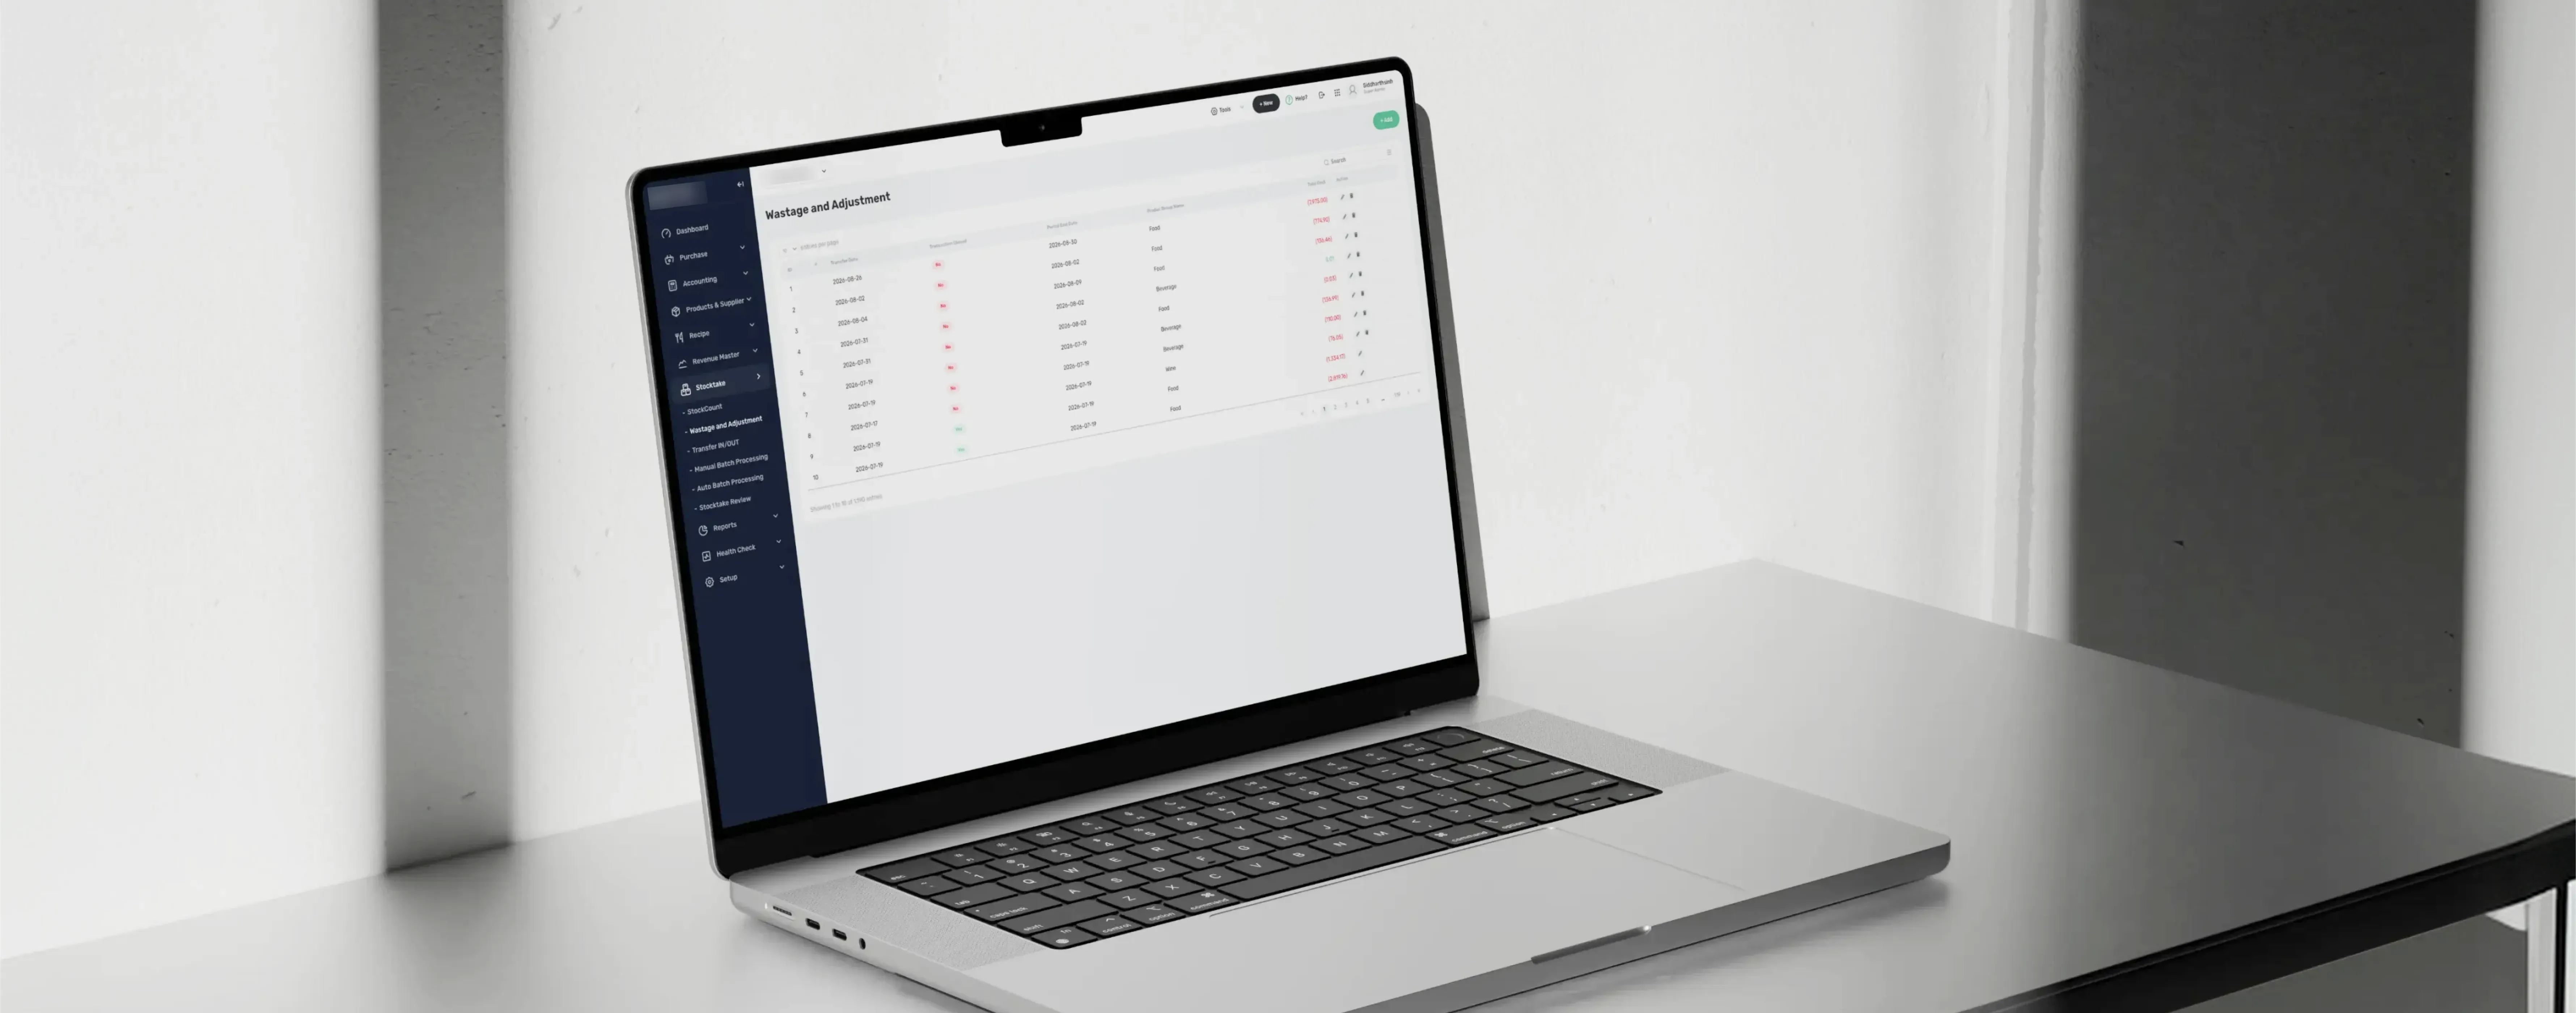
Discover how restaurant wastage and stock transfer control help track inventory movement, reduce product waste, and improve stock visibility across locations.

Discover how restaurant inventory control solutions help manage products, improve stock visibility, reduce manual work, and support efficient operations.
From ML pipeline design and CI/CD automation to model monitoring, retraining, and governance, we cover every layer of the MLOps lifecycle.
Design and automate end-to-end ML workflows, from data ingestion, preprocessing, and feature engineering to model training, evaluation, and versioned artifact storage.
Implement continuous integration and continuous delivery pipelines for ML models with automated testing, validation gates, canary rollouts, and rollback mechanisms.
Monitor model performance, data distribution, and prediction quality in real time, with automated alerts and triggers for retraining when drift thresholds are breached.
Build automated retraining pipelines that ingest fresh data, retrain models, run evaluation comparisons, and promote the best model to production, with full audit trails.
Design centralised feature stores that enable consistent, reusable, and versioned feature sets across multiple ML models, reducing training/serving skew and accelerating experimentation.
Implement model explainability (SHAP, LIME), bias detection, audit logging, and compliance reporting for regulated industries, including finance, healthcare, and insurance.
Design and automate end-to-end ML workflows, from data ingestion, preprocessing, and feature engineering to model training, evaluation, and versioned artifact storage.
Implement continuous integration and continuous delivery pipelines for ML models with automated testing, validation gates, canary rollouts, and rollback mechanisms.
Monitor model performance, data distribution, and prediction quality in real time, with automated alerts and triggers for retraining when drift thresholds are breached.
Build automated retraining pipelines that ingest fresh data, retrain models, run evaluation comparisons, and promote the best model to production, with full audit trails.
Design centralised feature stores that enable consistent, reusable, and versioned feature sets across multiple ML models, reducing training/serving skew and accelerating experimentation.
Implement model explainability (SHAP, LIME), bias detection, audit logging, and compliance reporting for regulated industries, including finance, healthcare, and insurance.
We bring together ML engineering, DevOps, data engineering, and cloud infrastructure expertise to build MLOps systems that are observable, reproducible, and built to last.
Orchestrate complex multi-step ML workflows with tools like Apache Airflow, Prefect, and Kubeflow Pipelines, with dependency management, scheduling, and failure recovery.
Track every experiment, hyperparameter, metric, and artefact with MLflow or Weights & Biases, and maintain a centralised model registry with staging, production, and archived versions.
Deploy models as low-latency REST or gRPC endpoints using BentoML, Triton Inference Server, or Ray Serve, with batching, caching, and auto-scaling for high-throughput workloads.
Build robust data pipelines that clean, transform, validate, and version training data, ensuring your ML models are always trained on high-quality, consistent, and reproducible datasets.
Stay ahead with practical guides, case studies, and technical deep-dives on MLOps best practices, model monitoring, CI/CD for ML, and production AI deployment.

Discover how to prepare your ecommerce store for agentic AI, from AI-powered shopping experiences to automation, personalization, and smarter commerce.

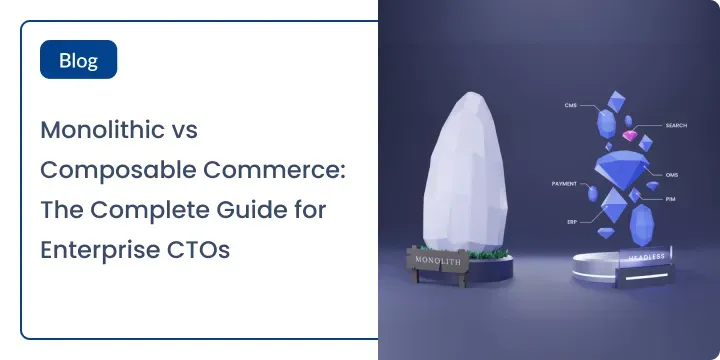
80% of enterprises are moving toward composable commerce. Compare monolithic vs. composable architecture and find the right fit with Cinovic’s free architecture assessment.

US social commerce hits $109.4B in 2026. TikTok Shop converts at 4.7%, more than double Instagram. Discover how zero-click commerce works across TikTok, Instagram, Google, and what your ecommerce store needs to do now. Free audit from Cinovic.
Book a free consultation and discover how our MLOps services can accelerate your model deployment, eliminate drift, and give your team full control over ML in production.
MLOps (Machine Learning Operations) is the practice of automating and streamlining the deployment, monitoring, and lifecycle management of ML models in production, bridging the gap between data science and software engineering.
DevOps automates software deployment and operations. MLOps extends DevOps principles specifically for machine learning — adding model versioning, data pipeline management, drift detection, and automated retraining to the standard CI/CD lifecycle.
We work with AWS SageMaker, Azure ML, Google Vertex AI, Kubeflow, MLflow, Weights & Biases, BentoML, Triton Inference Server, Apache Airflow, Prefect, and more, selecting the best stack for your cloud environment and scale.
Model drift occurs when a model's predictions become less accurate over time as real-world data changes. We handle it with continuous monitoring, statistical drift detection (PSI, KL divergence), automated alerts, and triggered retraining pipelines.
A basic MLOps setup with CI/CD and monitoring can be implemented in 3–6 weeks. A fully automated pipeline with feature store, experiment tracking, model registry, and governance reporting typically takes 8–14 weeks, depending on existing infrastructure.