Restaurants & Hospitality
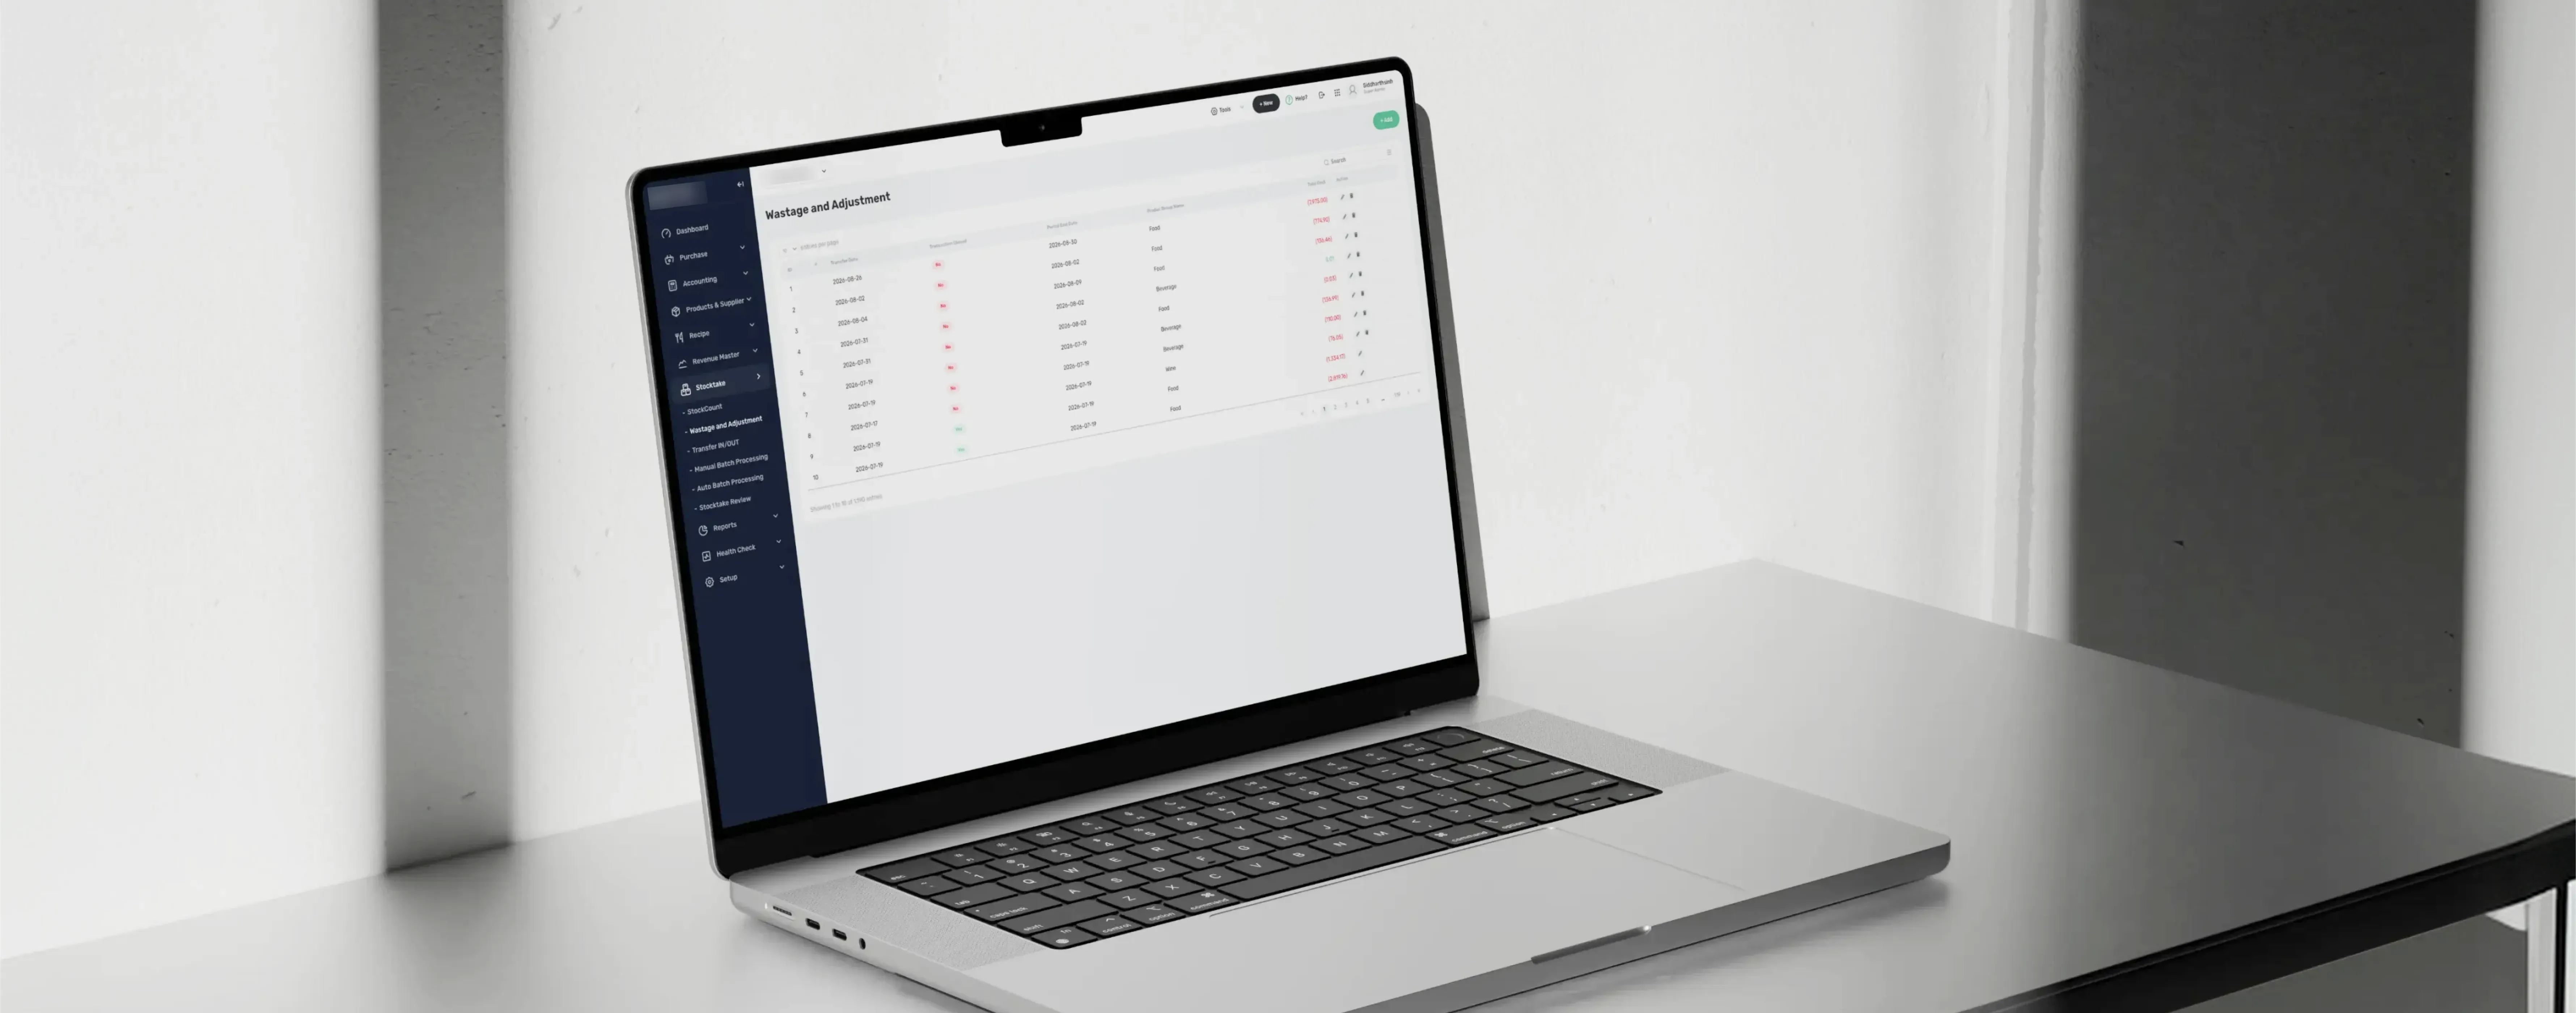
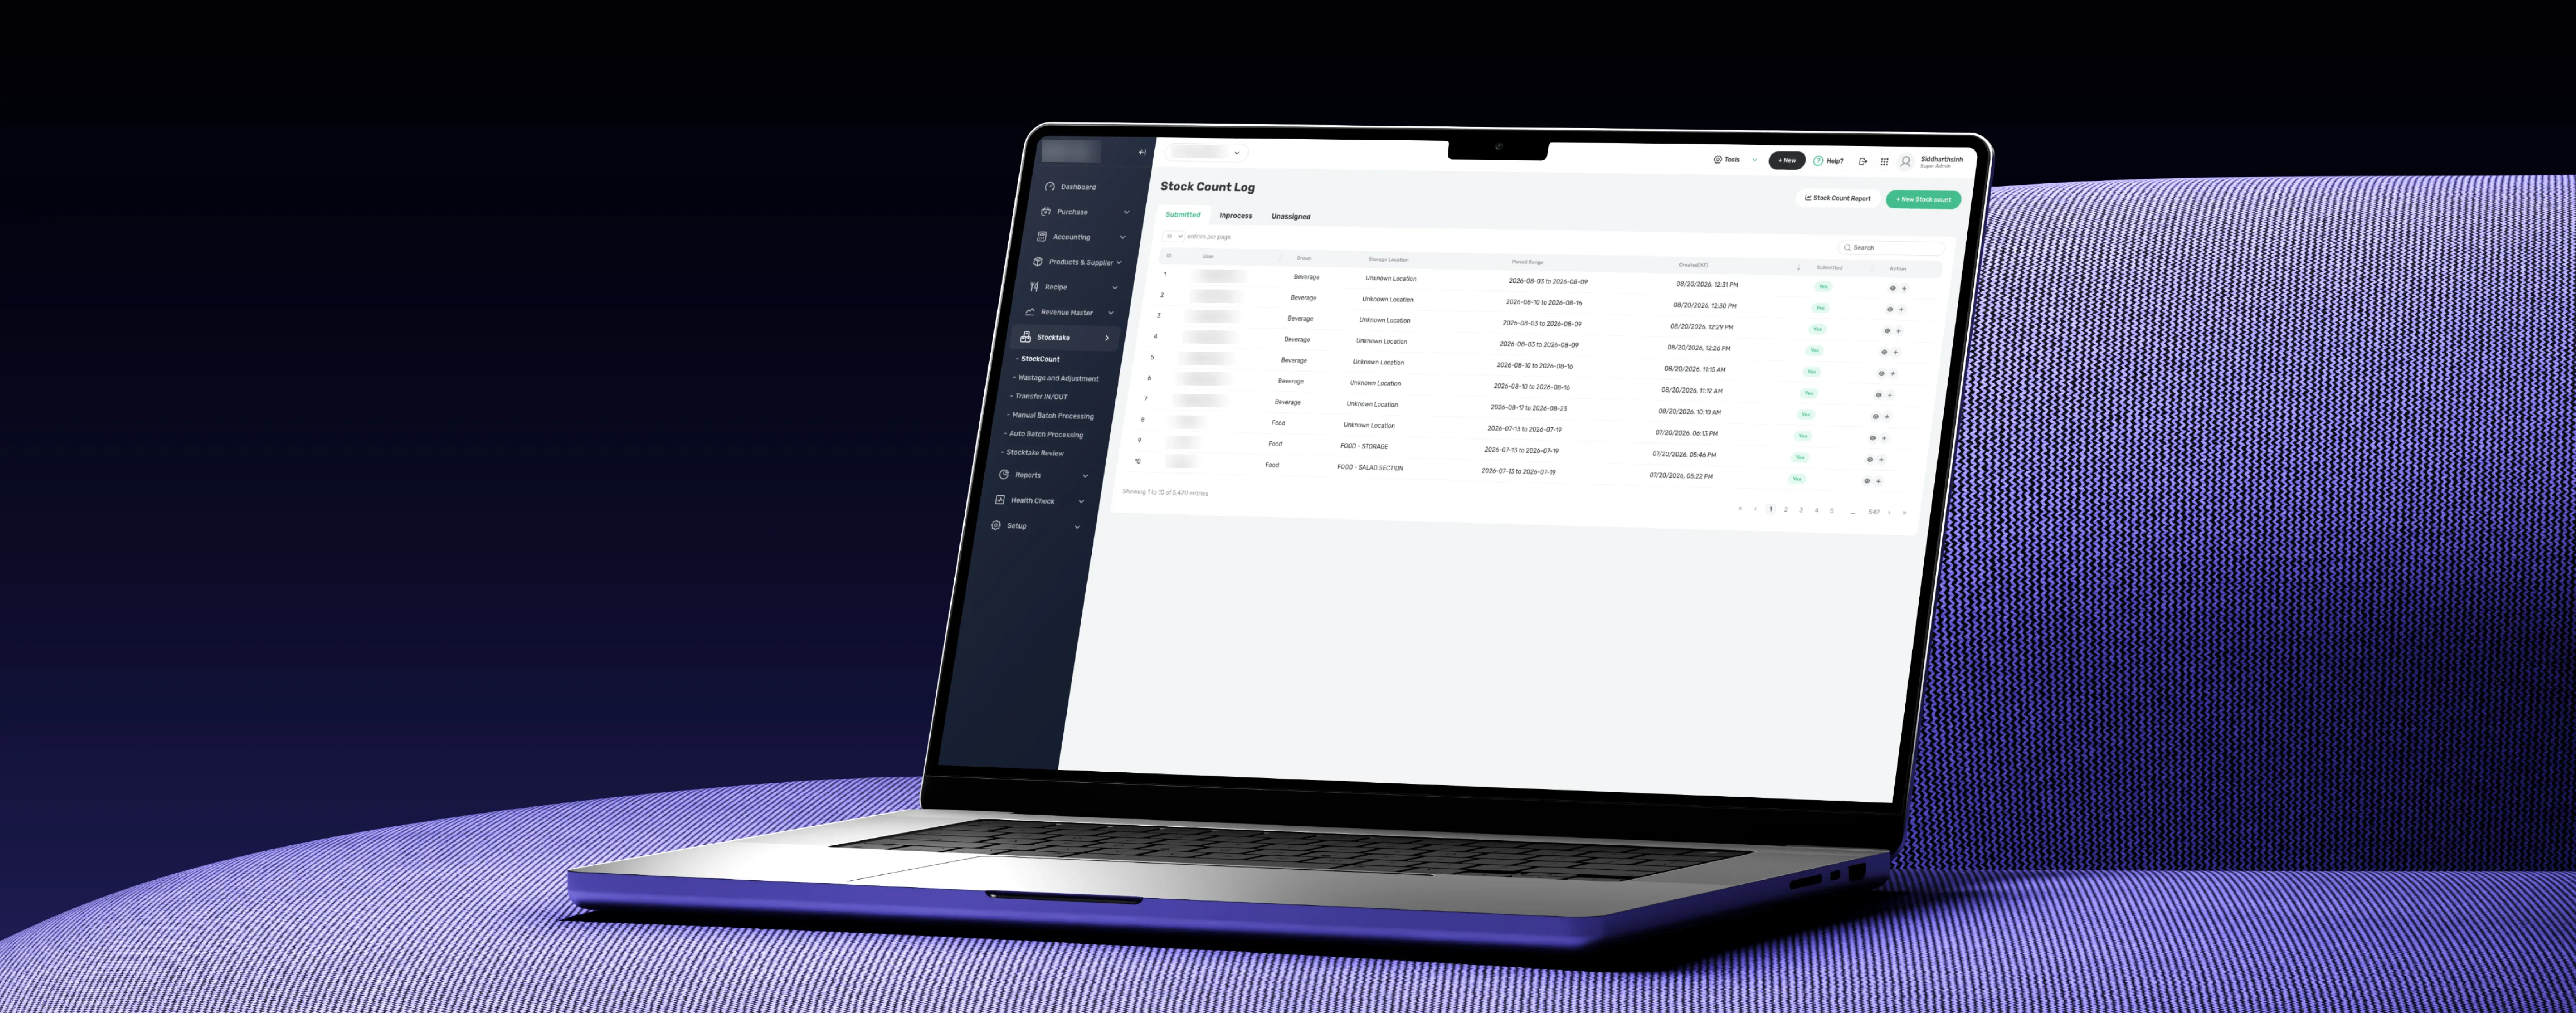
Restaurant Wastage & Stock Transfer Control
Discover how restaurant wastage and stock transfer control help track inventory movement, reduce product waste, and improve stock visibility across locations.
View Case Study
From on-premise data warehouse migration and Hadoop retirement to legacy ETL re-engineering, modern data stack adoption, and data governance transformation, Cinovic modernises your data infrastructure so your teams stop fighting old systems and start making decisions in real time.
We partner with CTOs, data engineering leaders, and analytics heads at organisations where legacy data systems have become the biggest bottleneck to growth, slowing delivery, blocking AI adoption, and costing more to maintain than to replace.
We don't modernise data for the sake of technology, we modernise it to unlock the analytics, AI, and operational capabilities your business needs to compete. Every modernisation engagement starts with the business outcome, not the tech stack.
Real data modernisation projects. Real infrastructure transformation outcomes. See how Cinovic has helped organisations move from brittle, expensive legacy systems to modern, scalable, AI-ready data platforms.
Discover how restaurant wastage and stock transfer control help track inventory movement, reduce product waste, and improve stock visibility across locations.
Discover how restaurant inventory control solutions help manage products, improve stock visibility, reduce manual work, and support efficient operations.
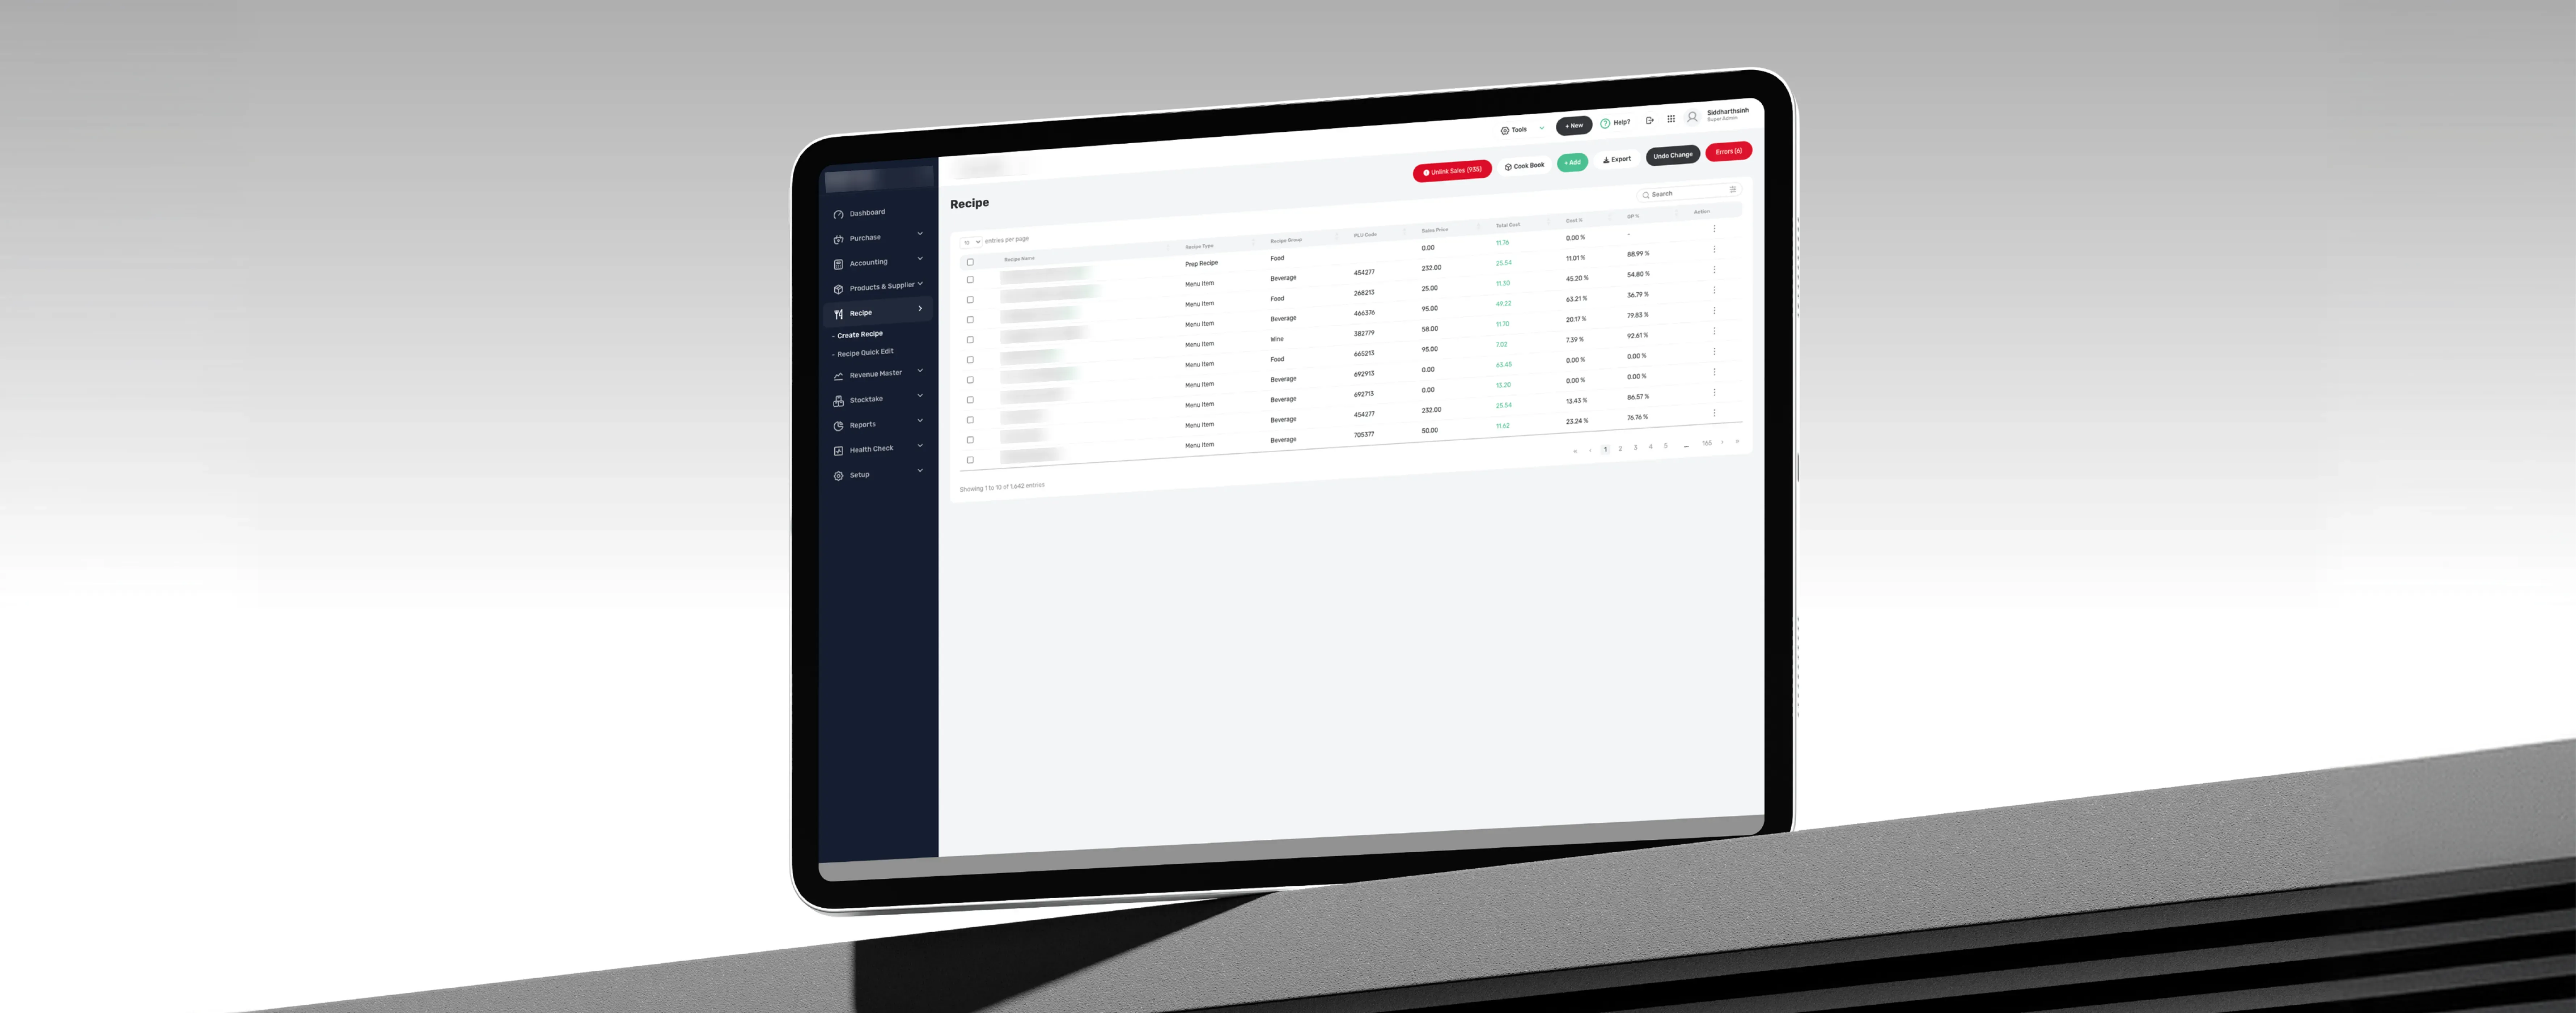
Discover how recipe and menu control solutions help kitchens manage recipes, standardize menus, and maintain consistent food operations across locations.
From on-premise data warehouse migration and Hadoop retirement to legacy ETL re-engineering, modern data stack adoption, data governance transformation, and AI readiness enablement, we modernise every layer of your data infrastructure.
Migrate from on-premises data warehouses, SQL Server, Oracle, Teradata, Netezza, IBM DB2, Greenplum, to modern cloud platforms: Snowflake, BigQuery, Amazon Redshift, or Azure Synapse, with full schema redesign, data migration, ETL re-engineering, historical data validation, query optimisation, and zero-downtime cutover.
Retire on-premises Hadoop clusters safely, re-engineering Hive, MapReduce, Pig, Oozie, and Sqoop workloads as optimised PySpark pipelines on Databricks, AWS EMR, or Google Dataproc, migrating HDFS data to cloud object storage, and implementing open table formats (Delta Lake, Iceberg) for reliable lakehouse architecture.
Re-engineer legacy ETL jobs, SSIS packages, Oracle Data Integrator mappings, Informatica workflows, DataStage jobs, and custom SQL stored procedure pipelines as modern ELT pipelines using dbt transformations, Apache Airflow orchestration, and cloud-native ingestion tools like Fivetran or Airbyte.
Adopt the modern data stack in a structured, sustainable way, selecting and implementing the right tools for ingestion (Fivetran, Airbyte), transformation (dbt), orchestration (Airflow, Prefect), warehousing (Snowflake, BigQuery), and observability (Monte Carlo, Great Expectations), with DataOps CI/CD pipelines, testing standards, and documentation practices your team will actually use.
Upgrade legacy data governance from manual spreadsheet-based processes to modern automated frameworks, implementing data catalogues (DataHub, Alation, Collibra), automated column-level lineage tracking, PII classification and masking, business glossary management, data quality SLAs, and GDPR/CCPA compliance controls that scale with your data volume.
Prepare your data infrastructure for AI and ML adoption — redesigning data models for feature engineering, implementing feature stores, enabling vector database integration for LLM-powered applications, establishing ML data quality standards, and building the governed, versioned, reproducible data pipelines that production ML models demand.
Migrate from on-premises data warehouses, SQL Server, Oracle, Teradata, Netezza, IBM DB2, Greenplum, to modern cloud platforms: Snowflake, BigQuery, Amazon Redshift, or Azure Synapse, with full schema redesign, data migration, ETL re-engineering, historical data validation, query optimisation, and zero-downtime cutover.
Retire on-premises Hadoop clusters safely, re-engineering Hive, MapReduce, Pig, Oozie, and Sqoop workloads as optimised PySpark pipelines on Databricks, AWS EMR, or Google Dataproc, migrating HDFS data to cloud object storage, and implementing open table formats (Delta Lake, Iceberg) for reliable lakehouse architecture.
Re-engineer legacy ETL jobs, SSIS packages, Oracle Data Integrator mappings, Informatica workflows, DataStage jobs, and custom SQL stored procedure pipelines as modern ELT pipelines using dbt transformations, Apache Airflow orchestration, and cloud-native ingestion tools like Fivetran or Airbyte.
Adopt the modern data stack in a structured, sustainable way, selecting and implementing the right tools for ingestion (Fivetran, Airbyte), transformation (dbt), orchestration (Airflow, Prefect), warehousing (Snowflake, BigQuery), and observability (Monte Carlo, Great Expectations), with DataOps CI/CD pipelines, testing standards, and documentation practices your team will actually use.
Upgrade legacy data governance from manual spreadsheet-based processes to modern automated frameworks, implementing data catalogues (DataHub, Alation, Collibra), automated column-level lineage tracking, PII classification and masking, business glossary management, data quality SLAs, and GDPR/CCPA compliance controls that scale with your data volume.
Prepare your data infrastructure for AI and ML adoption — redesigning data models for feature engineering, implementing feature stores, enabling vector database integration for LLM-powered applications, establishing ML data quality standards, and building the governed, versioned, reproducible data pipelines that production ML models demand.
We don't treat modernisation as a migration checkbox; we apply a proven four-phase methodology that covers discovery, architecture design, phased migration, and post-modernisation optimisation to ensure your modern data platform delivers immediate and compounding business value.
Before any modernisation begins, we conduct a comprehensive legacy data assessment, cataloguing all data sources, pipelines, ETL jobs, dependencies, data quality issues, and business logic, scoring each workload by modernisation complexity, business value, and risk to produce a prioritised modernisation backlog and phased roadmap.
Legacy systems accumulate years of data quality debt, duplicate records, broken referential integrity, inconsistent formats, undocumented business rules, and silent data errors. We audit, profile, remediate, and document your data quality issues before migration so your modern platform starts with clean, trusted data, not legacy debt in a new wrapper.
We run legacy and modern systems in parallel during migration, comparing outputs row by row, validating business logic preservation, running reconciliation reports for finance and operations, and using phased DNS or API cutover strategies to switch traffic to the modern platform only when full equivalence is confirmed.
Going live is the beginning, not the end. We provide 30+ days of post-modernisation hypercare, query performance tuning, cost optimisation, pipeline reliability monitoring, team training on modern tools (dbt, Airflow, Snowflake), DataOps workflow establishment, and ongoing optimisation to ensure your modern platform performs and evolves beyond the initial delivery.
Stay ahead with practical modernisation guides, migration checklists, case studies, and deep-dives on Hadoop retirement, cloud data warehouse migration, legacy ETL re-engineering, modern data stack adoption, and building AI-ready data infrastructure.
Discover how to prepare your ecommerce store for agentic AI, from AI-powered shopping experiences to automation, personalization, and smarter commerce.
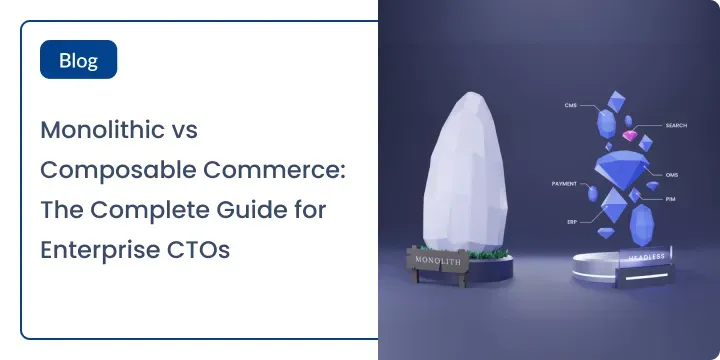
80% of enterprises are moving toward composable commerce. Compare monolithic vs. composable architecture and find the right fit with Cinovic’s free architecture assessment.
US social commerce hits $109.4B in 2026. TikTok Shop converts at 4.7%, more than double Instagram. Discover how zero-click commerce works across TikTok, Instagram, Google, and what your ecommerce store needs to do now. Free audit from Cinovic.
Tell us about your legacy data environment, the systems you're running, the pain they're causing, and the business outcomes you want to unlock — and we'll deliver an honest modernisation assessment and phased roadmap within 48 hours.
Data modernisation is the process of replacing legacy data infrastructure, on-premise data warehouses, outdated ETL tools, ageing Hadoop clusters, and fragmented data silos with modern, cloud-native, scalable data platforms. It matters now because legacy infrastructure is the #1 barrier to AI adoption, real-time analytics, and the data quality standards that modern businesses require. Organisations that delay modernisation pay compounding costs — in maintenance overhead, lost analytics velocity, and missed AI opportunities.
A data migration moves data from one place to another, it's a technical operation. Data modernisation is a broader transformation programme that includes migration but also re-engineers your data pipelines, redesigns your data models, upgrades your governance frameworks, adopts modern tooling (dbt, Airflow, Snowflake), and upskills your data team. The goal of migration is to move. The goal of modernisation is to transform your organisation's relationship with data.
Data integrity is our highest priority throughout every modernisation. We run comprehensive pre-migration data profiling and audits, execute migrations in controlled phases with row-count reconciliation after every run, operate legacy and modern systems in parallel for full output comparison, run business-logic validation with finance and operations stakeholders, and confirm full data equivalence before any cutover. We have delivered zero data loss across every modernisation engagement we have completed.
Yes, business continuity is a design constraint, not an afterthought, in every modernisation we deliver. We use phased migration strategies that move workloads incrementally, run legacy and modern systems in parallel during transition, schedule high-risk cutovers during low-traffic windows, maintain full rollback capability throughout, and provide 30+ days of post-launch hypercare, so your team is never left alone during the transition period.
Timelines depend on legacy complexity and scope. A focused single-source cloud warehouse migration (e.g. SQL Server to Snowflake) typically takes 8–16 weeks. A full ETL estate re-engineering programme with 100–300 jobs takes 12–24 weeks. A large-scale Hadoop retirement with petabyte-scale data migration takes 16–32 weeks. Enterprise-wide modernisation programmes covering multiple legacy systems, governance uplift, and team enablement run 6–18 months in phased delivery. We scope everything in detail during your free legacy data assessment.