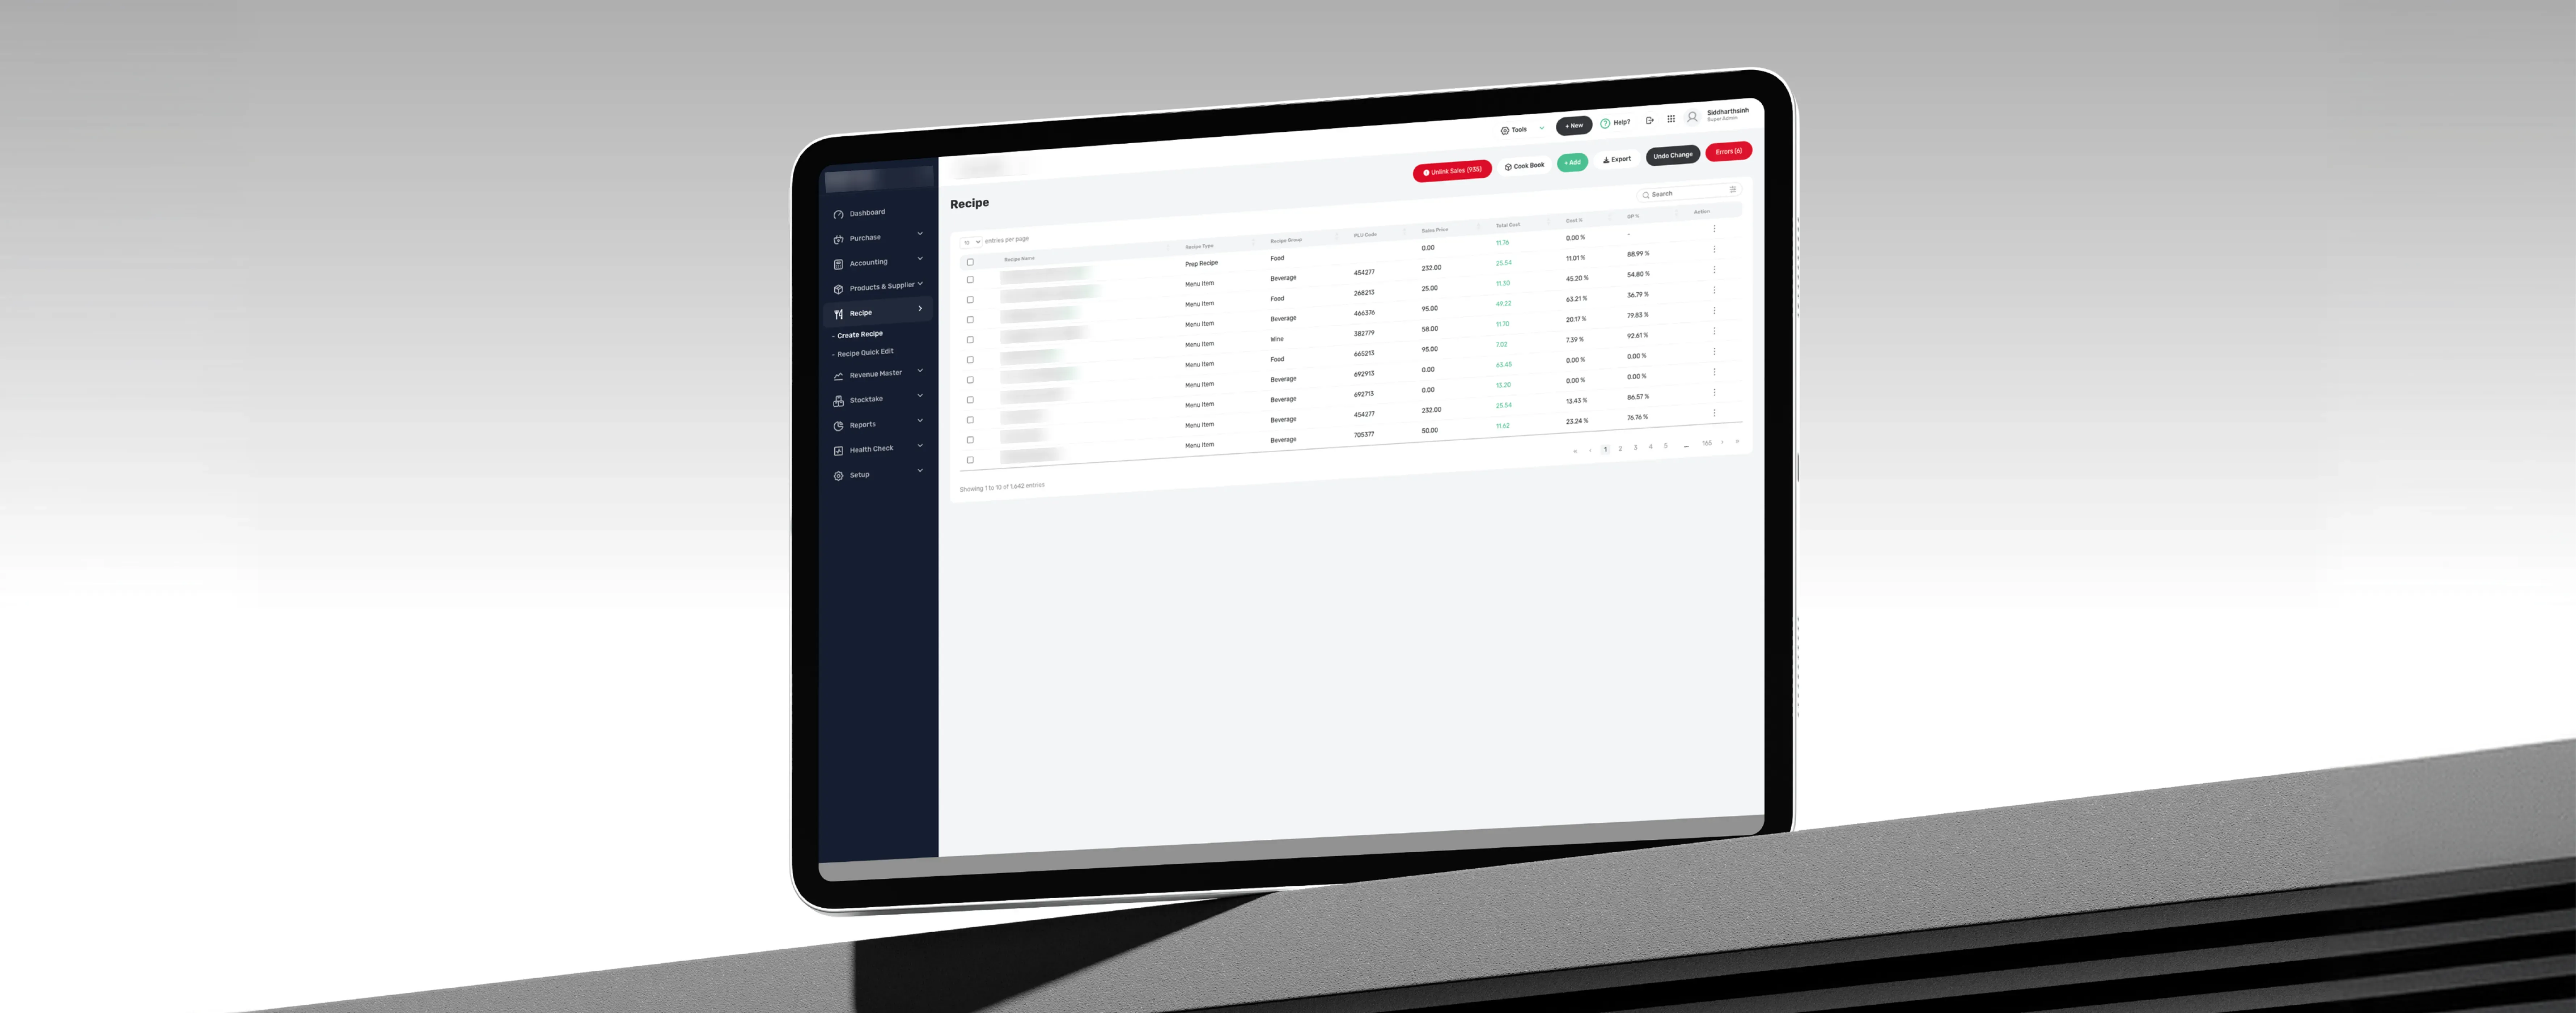
Restaurant Product & Recipe Data Management Platform
Explore a restaurant product and recipe data platform designed to centralize product information, manage recipes, and improve operational data consistency.
From distributed data lake architecture and Apache Spark engineering to real-time Kafka streaming, Databricks lakehouse builds, and cloud-native big data pipelines — Cinovic engineers big data platforms that turn terabytes and petabytes of raw data into reliable, actionable intelligence.

We partner with engineering teams and data leaders at companies where data volume, velocity, and variety have outgrown conventional databases — and who need big data infrastructure that is reliable, cost-efficient, and built to scale.
We don't treat big data as a buzzword — we architect distributed processing systems, tune Spark jobs for cost and latency, design fault-tolerant streaming pipelines, and build data lakes that don't become data swamps.
Real big data engineering projects. Real processing performance outcomes. See how Cinovic has helped data-intensive businesses tame massive data volumes, cut processing times, and unlock analytics at scale.

Explore a restaurant product and recipe data platform designed to centralize product information, manage recipes, and improve operational data consistency.

Discover how restaurant wastage and stock transfer control help track inventory movement, reduce product waste, and improve stock visibility across locations.

Discover how restaurant inventory control solutions help manage products, improve stock visibility, reduce manual work, and support efficient operations.
From distributed data lake architecture and Apache Spark engineering to real-time Kafka streaming, Hadoop modernisation, Databricks lakehouse builds, and cloud-native big data pipelines — we cover the full big data engineering lifecycle.
Design and build enterprise data lakes on AWS S3, Google Cloud Storage, or Azure Data Lake Storage Gen2 — with structured zone architecture (Raw/Bronze, Cleansed/Silver, Curated/Gold), open table format implementation (Delta Lake, Apache Iceberg, Apache Hudi), metadata cataloguing, access controls, and data quality enforcement at every layer.
Build, tune, and optimise Apache Spark and PySpark data pipelines — from batch ETL and large-scale data transformation to ML feature engineering and graph processing — with job profiling, executor tuning, partition optimisation, broadcast join strategies, and AQE (Adaptive Query Execution) configuration.
Design and implement real-time streaming data platforms using Apache Kafka, Apache Flink, and Spark Structured Streaming — for event-driven analytics, fraud detection, IoT data ingestion, real-time personalisation, CDC pipelines, and operational data streaming at millions of events per second.
Architect and implement Databricks lakehouse platforms — Unity Catalog setup and governance, Delta Live Tables pipeline engineering, Databricks Workflows orchestration, MLflow integration for ML pipelines, and multi-cluster auto-scaling configurations for cost-efficient big data processing at any scale.
Migrate from on-premise Hadoop clusters (HDFS, Hive, MapReduce, HBase, Oozie) to modern cloud-native big data platforms on AWS EMR, Google Dataproc, Azure HDInsight, or Databricks — re-engineering legacy MapReduce and Hive jobs as optimised PySpark, with full data migration and zero operational disruption.
Build fully managed, cloud-native big data pipelines using AWS Glue, Google Cloud Dataflow, Azure Data Factory, and serverless processing — eliminating infrastructure management overhead and reducing pipeline maintenance burden while scaling automatically to any data volume.
Design and build enterprise data lakes on AWS S3, Google Cloud Storage, or Azure Data Lake Storage Gen2 — with structured zone architecture (Raw/Bronze, Cleansed/Silver, Curated/Gold), open table format implementation (Delta Lake, Apache Iceberg, Apache Hudi), metadata cataloguing, access controls, and data quality enforcement at every layer.
Build, tune, and optimise Apache Spark and PySpark data pipelines — from batch ETL and large-scale data transformation to ML feature engineering and graph processing — with job profiling, executor tuning, partition optimisation, broadcast join strategies, and AQE (Adaptive Query Execution) configuration.
Design and implement real-time streaming data platforms using Apache Kafka, Apache Flink, and Spark Structured Streaming — for event-driven analytics, fraud detection, IoT data ingestion, real-time personalisation, CDC pipelines, and operational data streaming at millions of events per second.
Architect and implement Databricks lakehouse platforms — Unity Catalog setup and governance, Delta Live Tables pipeline engineering, Databricks Workflows orchestration, MLflow integration for ML pipelines, and multi-cluster auto-scaling configurations for cost-efficient big data processing at any scale.
Migrate from on-premise Hadoop clusters (HDFS, Hive, MapReduce, HBase, Oozie) to modern cloud-native big data platforms on AWS EMR, Google Dataproc, Azure HDInsight, or Databricks — re-engineering legacy MapReduce and Hive jobs as optimised PySpark, with full data migration and zero operational disruption.
Build fully managed, cloud-native big data pipelines using AWS Glue, Google Cloud Dataflow, Azure Data Factory, and serverless processing — eliminating infrastructure management overhead and reducing pipeline maintenance burden while scaling automatically to any data volume.
We combine distributed systems engineering, cloud infrastructure expertise, and data architecture depth to build big data platforms that are observable, self-healing, cost-optimised, and built to outlast today's data volumes.
Implement and manage open table formats — Delta Lake, Apache Iceberg, and Apache Hudi — enabling ACID transactions, time travel queries, schema evolution, and efficient upserts on massive data lakes that traditional Parquet/ORC files cannot support, enabling reliable lakehouse architecture at any scale.
Implement end-to-end big data observability — Spark job monitoring with Databricks or AWS CloudWatch, pipeline SLA tracking, data freshness alerts, anomaly detection on data volumes and schema changes, lineage tracking with OpenLineage or Marquez, and automated alerting for failed or stalled jobs.
Implement enterprise big data security frameworks — column-level and row-level access controls, PII detection and masking at scale using Apache Ranger or Unity Catalog, encryption at rest and in transit, GDPR/CCPA-compliant data handling, and audit logging across all data access events.
Build the big data foundations that power enterprise AI — large-scale feature engineering pipelines with Spark, distributed training data preparation, vector embeddings at scale, LLM pre-training data pipelines, and Databricks MLflow-managed experiment tracking and model versioning across petabyte-scale datasets.
Stay ahead with practical architecture guides, framework comparisons, performance deep-dives, and case studies on Apache Spark, Kafka streaming, Databricks, Hadoop modernisation, data lake design, and petabyte-scale data engineering.

Discover how to prepare your ecommerce store for agentic AI, from AI-powered shopping experiences to automation, personalization, and smarter commerce.

80% of enterprises are moving toward composable commerce. Compare monolithic vs. composable architecture and find the right fit with Cinovic’s free architecture assessment.

US social commerce hits $109.4B in 2026. TikTok Shop converts at 4.7%, more than double Instagram. Discover how zero-click commerce works across TikTok, Instagram, Google, and what your ecommerce store needs to do now. Free audit from Cinovic.
Tell us about your data volumes, your processing bottlenecks, and your analytics goals — and we'll give you an honest platform recommendation, architecture blueprint, and practical roadmap to a scalable, cost-efficient big data platform.
Big data services cover the design, engineering, and operation of distributed data systems built to handle data volumes, velocities, or variety that conventional databases and tools cannot manage. You need big data services when your queries are too slow for your data volumes, when you're ingesting millions of events per second in real time, when your data lake lacks governance and reliability, or when you're processing workloads measured in terabytes or petabytes.
Apache Spark is a unified distributed processing engine optimised for large-scale batch processing, ML workloads, and SQL analytics, with strong streaming capabilities via Spark Structured Streaming. Apache Flink is a dedicated stream processing framework built for true stateful real-time processing with lower latency and more precise event-time handling. For most organisations, Spark handles batch and near-real-time needs well. Flink is the better choice when you need sub-second streaming latency, complex event processing, or stateful stream joins at scale.
A data lake is a raw storage repository — typically S3, GCS, or ADLS — that stores structured, semi-structured, and unstructured data at low cost. A data lakehouse adds a structured, transactional layer on top of the data lake using open table formats like Delta Lake, Apache Iceberg, or Apache Hudi — enabling ACID transactions, schema enforcement, time travel, and SQL analytics with data warehouse-like performance, directly on your lake storage.
For most organisations, cloud migration is the right path. On-premise Hadoop clusters carry high infrastructure, maintenance, and skills costs, while cloud-native alternatives like Databricks, AWS EMR, or Google Dataproc offer better performance, elastic scaling, and managed services. We evaluate your current Hadoop workloads, identify which jobs benefit most from cloud migration, and design a phased migration plan that minimises business disruption.
We build reliability into every layer of the big data stack — idempotent pipeline design so jobs can safely retry without data duplication, checkpointing in Spark and Flink streaming jobs, dead letter queues for failed records, automated alerting on job failures and data freshness SLA breaches, circuit breaker patterns for upstream source failures, and runbook-documented incident response procedures.