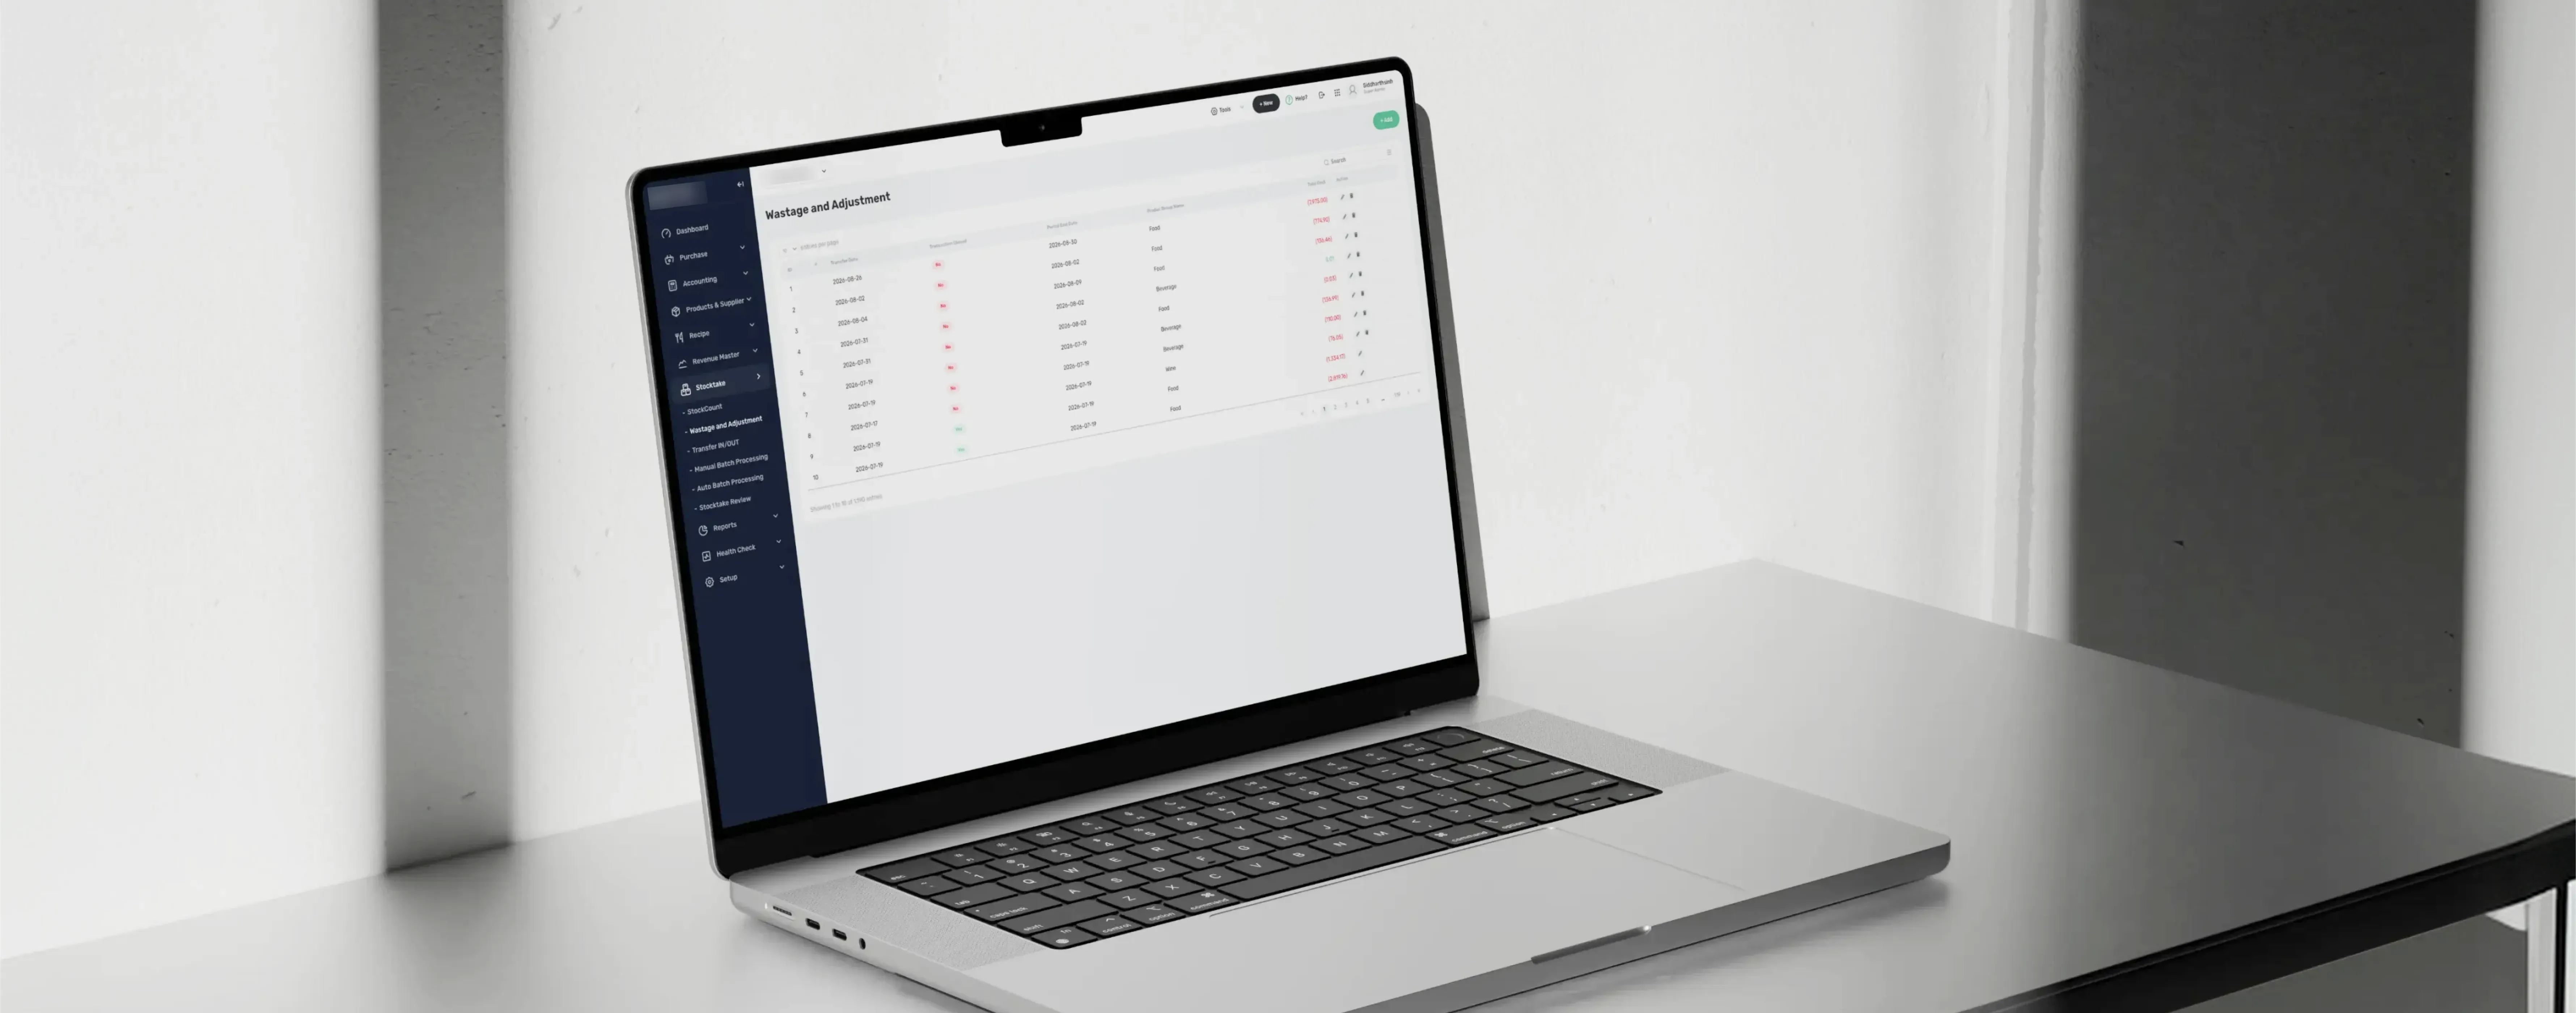
Restaurants & Hospitality
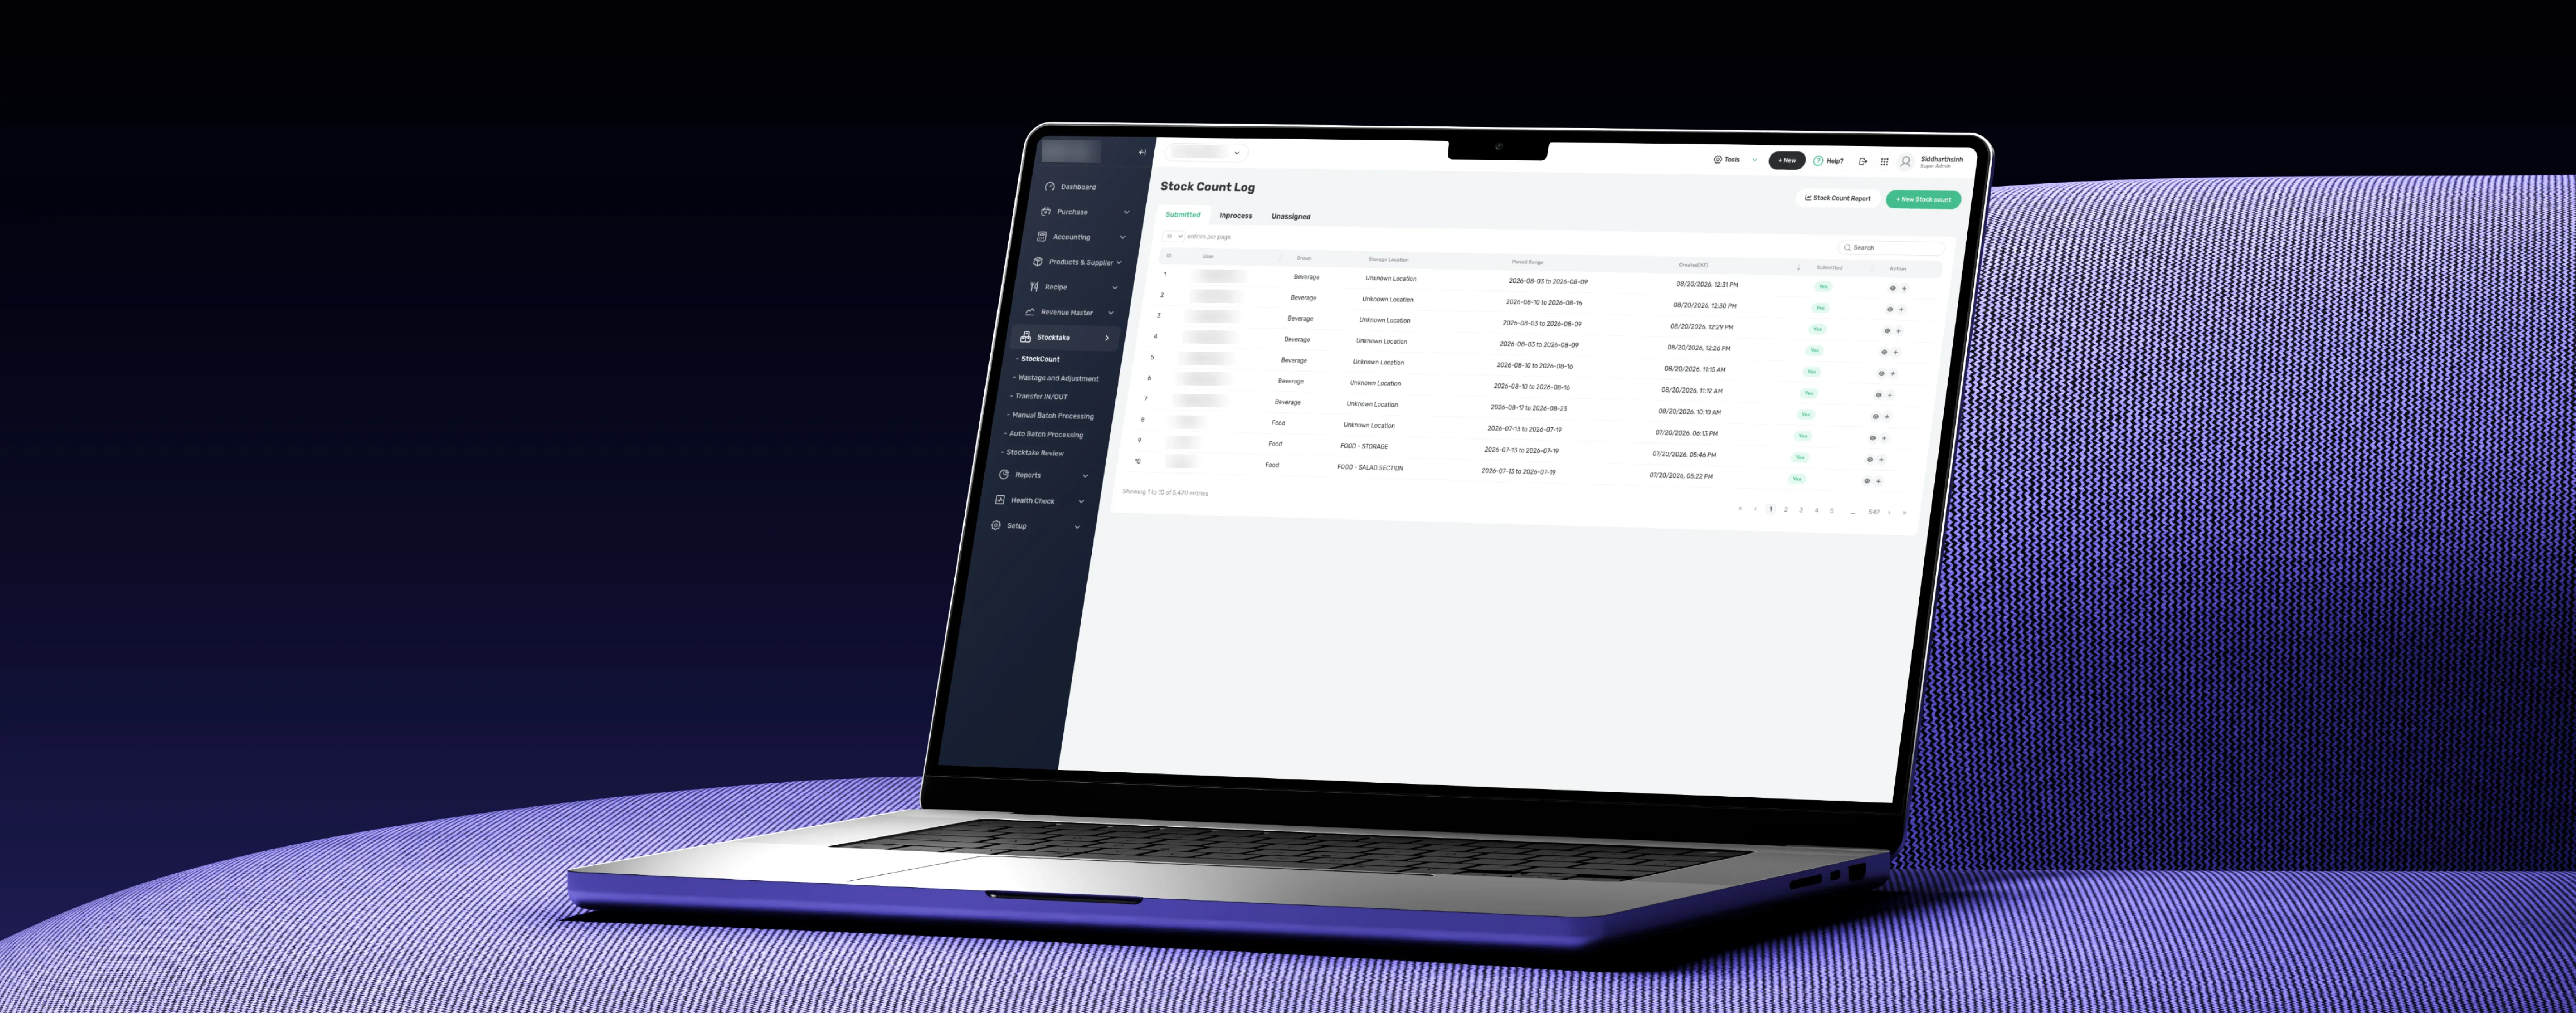
Restaurant Wastage & Stock Transfer Control
Discover how restaurant wastage and stock transfer control help track inventory movement, reduce product waste, and improve stock visibility across locations.
View Case Study
From real-time data pipelines and cloud data warehouses to lakehouse architecture, ETL automation, and advanced analytics, Cinovic engineers data systems that power accurate decisions, faster insights, and sustainable data-driven growth.
We partner with companies who understand that bad data infrastructure is a business risk, and who need a data engineering partner that delivers accuracy, reliability, and scale, not just dashboards.
We don't just build pipelines; we architect your entire data ecosystem: ingestion, transformation, storage, orchestration, and delivery — with a structured engineering process that gives every team a single source of trusted, real-time data.
Real data engineering projects. Real outcomes. See how Cinovic has helped companies eliminate data silos, accelerate analytics, and build data infrastructure that actually powers business decisions.
Discover how restaurant wastage and stock transfer control help track inventory movement, reduce product waste, and improve stock visibility across locations.
Discover how restaurant inventory control solutions help manage products, improve stock visibility, reduce manual work, and support efficient operations.
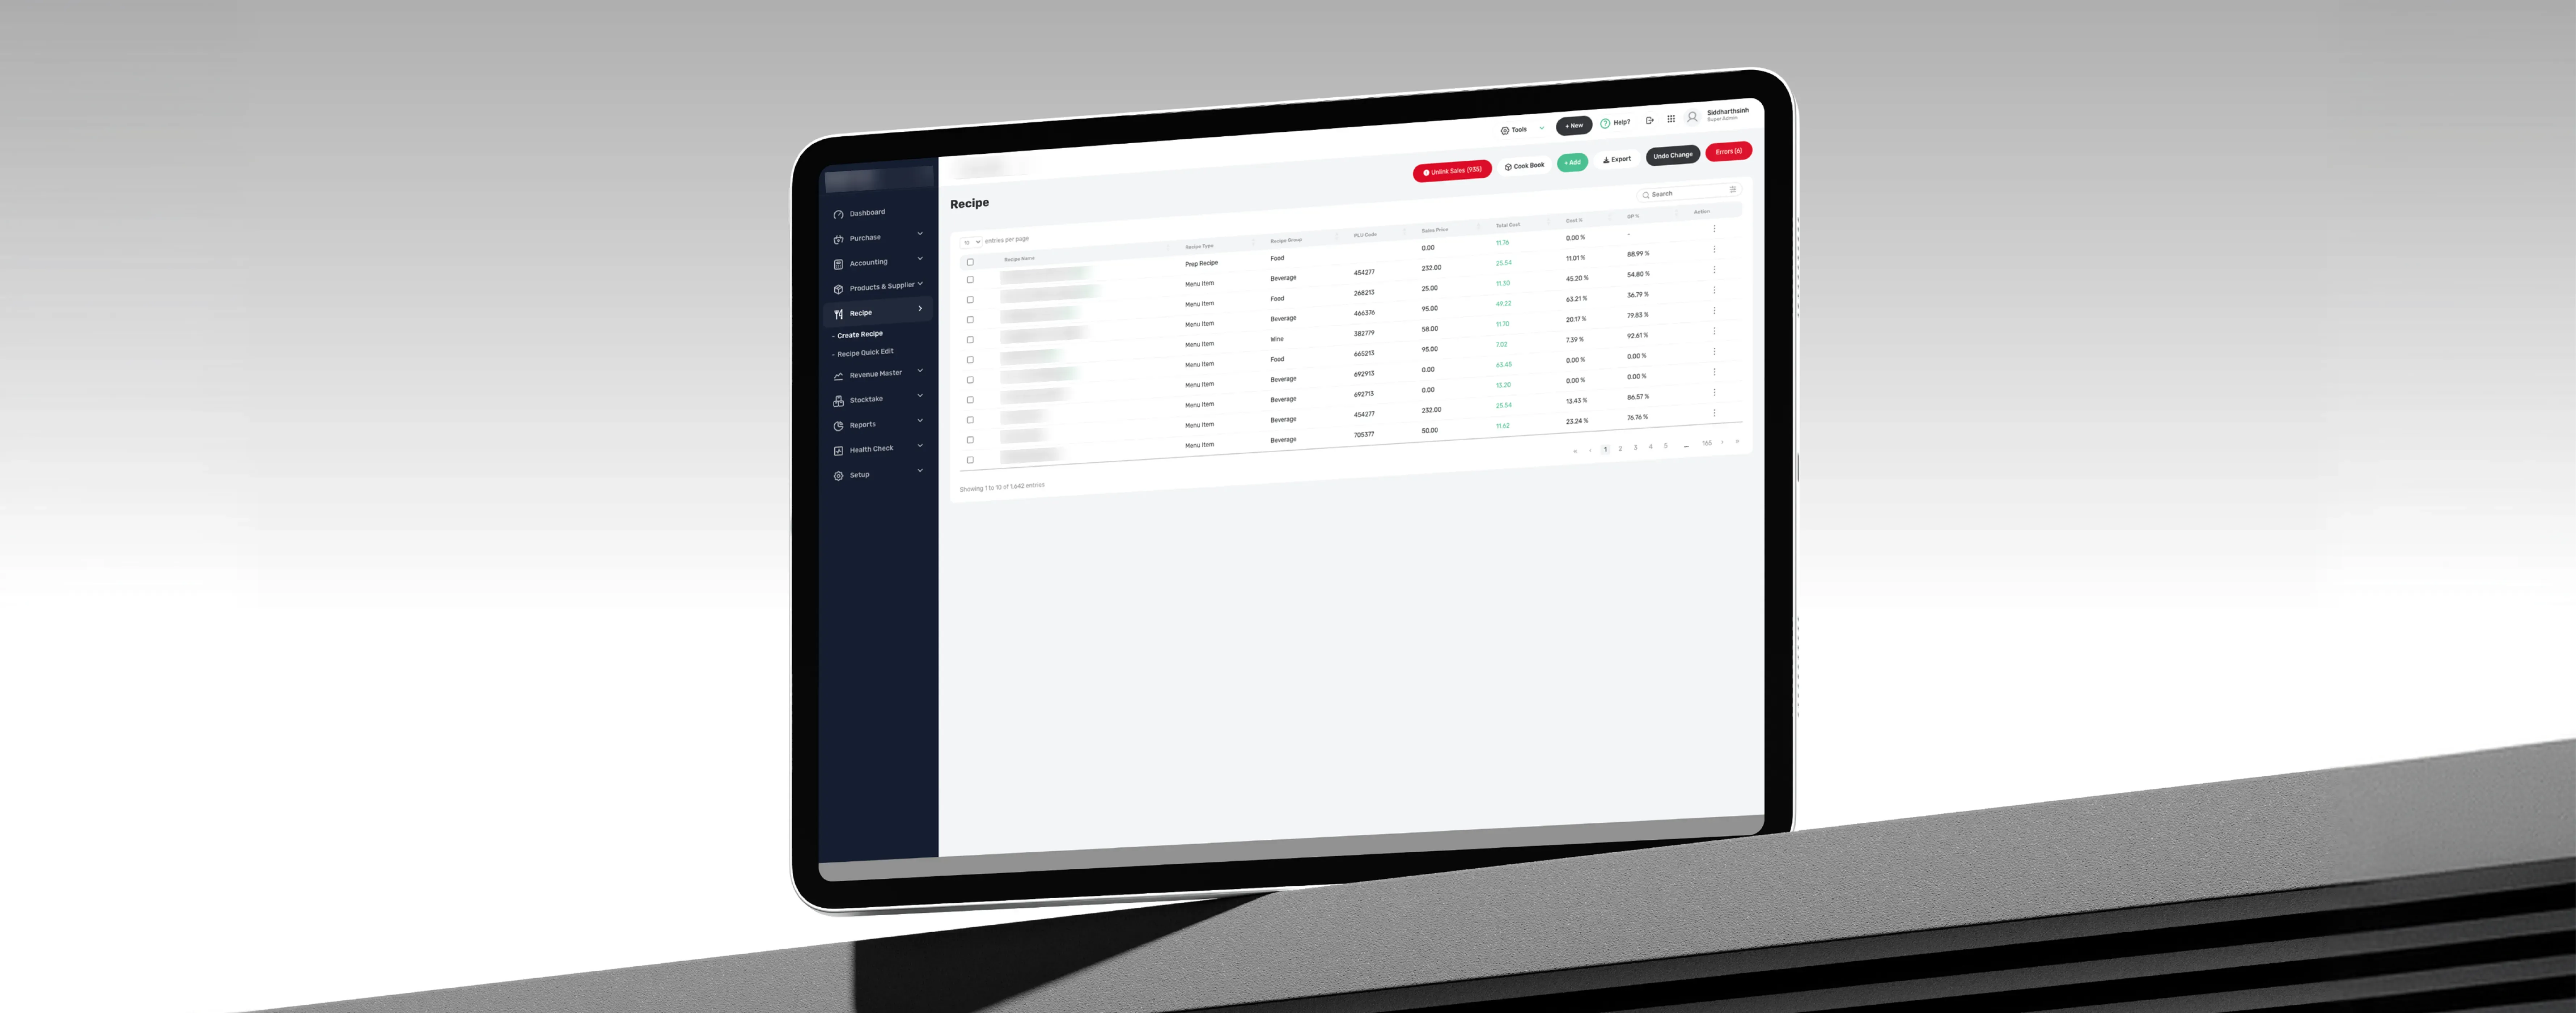
Discover how recipe and menu control solutions help kitchens manage recipes, standardize menus, and maintain consistent food operations across locations.
Whether you're building your first data pipeline, migrating to a cloud data warehouse, architecting a lakehouse, or scaling an existing data platform, we have a proven engineering approach, a dedicated data team, and a quality-first process for your project.
Design and build robust, scalable data pipelines, from simple ETL batch jobs to complex multi-source ELT architectures, using Apache Airflow, dbt, Spark, Kafka, and cloud-native pipeline services on AWS, GCP, and Azure. Full pipeline monitoring and alerting included.
Architect and deploy cloud data warehouses on Snowflake, Google BigQuery, Amazon Redshift, and Azure Synapse, with optimised schema design, partitioning strategies, cost controls, role-based access, and full integration with your BI tools and data pipelines.
Build modern lakehouse architectures combining the flexibility of data lakes with the reliability of data warehouses, using Databricks, Delta Lake, Apache Iceberg, and AWS S3 or Azure Data Lake Storage, giving you unified storage, ACID transactions, time-travel queries, and ML-ready data layers.
Design and deploy real-time streaming data systems using Apache Kafka, Apache Flink, Spark Structured Streaming, and AWS Kinesis, enabling event-driven architectures, real-time personalisation, live fraud detection, and sub-second analytics on high-volume data streams.
Build and maintain scalable data transformation layers using dbt (data build tool) creating modular, version-controlled SQL models, automated testing, documentation, and CI/CD pipelines for your analytics engineering workflow, fully integrated with Snowflake, BigQuery, or Redshift.
Implement end-to-end data observability across your entire data stack, including data lineage tracking, freshness and volume monitoring, schema change detection, anomaly alerting, SLA tracking, and integration with Great Expectations, Monte Carlo, or custom quality frameworks, ensuring trusted data at every layer.
Design and build robust, scalable data pipelines, from simple ETL batch jobs to complex multi-source ELT architectures, using Apache Airflow, dbt, Spark, Kafka, and cloud-native pipeline services on AWS, GCP, and Azure. Full pipeline monitoring and alerting included.
Architect and deploy cloud data warehouses on Snowflake, Google BigQuery, Amazon Redshift, and Azure Synapse, with optimised schema design, partitioning strategies, cost controls, role-based access, and full integration with your BI tools and data pipelines.
Build modern lakehouse architectures combining the flexibility of data lakes with the reliability of data warehouses, using Databricks, Delta Lake, Apache Iceberg, and AWS S3 or Azure Data Lake Storage, giving you unified storage, ACID transactions, time-travel queries, and ML-ready data layers.
Design and deploy real-time streaming data systems using Apache Kafka, Apache Flink, Spark Structured Streaming, and AWS Kinesis, enabling event-driven architectures, real-time personalisation, live fraud detection, and sub-second analytics on high-volume data streams.
Build and maintain scalable data transformation layers using dbt (data build tool) creating modular, version-controlled SQL models, automated testing, documentation, and CI/CD pipelines for your analytics engineering workflow, fully integrated with Snowflake, BigQuery, or Redshift.
Implement end-to-end data observability across your entire data stack, including data lineage tracking, freshness and volume monitoring, schema change detection, anomaly alerting, SLA tracking, and integration with Great Expectations, Monte Carlo, or custom quality frameworks, ensuring trusted data at every layer.
We don't improvise data architecture. Every engagement follows our structured 5-phase data engineering framework covering discovery, architecture design, pipeline build, quality validation, and production deployment, with full observability and rollback capability at every stage.
We audit your existing data landscape, cataloguing every source system, data type, volume, velocity, integration dependency, and business use case, before designing a target architecture that supports your current needs and scales with your 3-year data growth trajectory.
We build production-grade data pipelines with idempotent processing, automated retry logic, dead-letter queue handling, and full orchestration via Apache Airflow or Prefect, ensuring pipelines recover gracefully from failures and deliver consistent, complete data every run.
We implement automated data quality tests at every pipeline stage, schema contracts, null rate thresholds, row count validations, referential integrity checks, and statistical distribution monitoring, using Great Expectations, dbt tests, and custom validation frameworks, so data issues are caught before they reach dashboards.
We deploy data systems with end-to-end observability built in, data lineage graphs, pipeline health dashboards, freshness SLA alerts, cost monitoring, and automated incident escalation, and provide ongoing optimisation to reduce query costs, improve pipeline throughput, and maintain data quality as your business grows.
Stay ahead with practical guides on data pipeline design, cloud data warehouse architecture, lakehouse patterns, dbt best practices, and real-world case studies from our data engineering projects.
Discover how to prepare your ecommerce store for agentic AI, from AI-powered shopping experiences to automation, personalization, and smarter commerce.
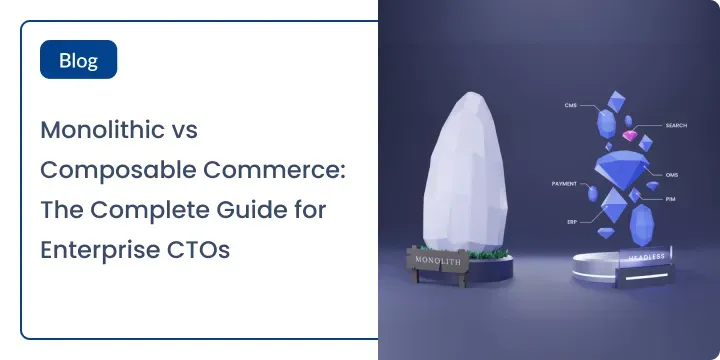
80% of enterprises are moving toward composable commerce. Compare monolithic vs. composable architecture and find the right fit with Cinovic’s free architecture assessment.
US social commerce hits $109.4B in 2026. TikTok Shop converts at 4.7%, more than double Instagram. Discover how zero-click commerce works across TikTok, Instagram, Google, and what your ecommerce store needs to do now. Free audit from Cinovic.
Tell us about your current data stack, your biggest data challenges, and your business goals, and we'll give you a clear architecture recommendation, gap analysis, and honest effort estimate within 48 hours.
Data engineering is the discipline of designing, building, and maintaining the systems, pipelines, and infrastructure that collect, transform, and deliver data reliably to the people and tools that need it. Without solid data engineering, your analysts spend 80% of their time cleaning data, your dashboards show stale or inaccurate numbers, and your AI and ML initiatives fail before they start. With mature data engineering, your entire organisation operates on a single source of trusted, real-time data.
A data warehouse (Snowflake, BigQuery, Redshift) is optimised for structured, query-ready analytical data, fast SQL queries, strong governance, but is expensive for raw storage. A data lake (AWS S3, ADLS) stores raw data of any type at low cost, but without structure, querying it is slow and unreliable. A lakehouse (Databricks, Delta Lake) combines both raw storage with warehouse-grade query performance, ACID transactions, and data governance. We help you choose and build the right architecture based on your specific data types, volumes, and analytical needs.
Timeline depends on complexity and scope. A focused ETL pipeline for a single data source typically takes 2–4 weeks. A multi-source data warehouse built with BI integration runs 6–12 weeks. A full enterprise data platform with lakehouse architecture, real-time streaming, and data quality frameworks takes 3–6 months. We provide a detailed project roadmap and phased delivery plan in your free architecture review.
Yes — we are cloud-agnostic and tool-agnostic. We work with AWS, Google Cloud, and Azure, and we integrate with all major data sources — databases (PostgreSQL, MySQL, Oracle, SQL Server), SaaS platforms (Salesforce, HubSpot, Stripe, Shopify), event streams (Kafka, Kinesis), and custom APIs. We assess your existing infrastructure in the discovery phase and design a data architecture that builds on what you already have, not one that forces you to start from scratch.
Data quality is engineered into every pipeline we build, not added afterwards. We implement automated quality tests at every pipeline stage: schema validation, null rate monitoring, row count reconciliation, referential integrity checks, and statistical distribution anomaly detection. Every pipeline runs with alerting on quality gate failures, and our data observability layer gives you full visibility into data freshness, lineage, and health, so issues are caught and resolved before they ever reach a dashboard or ML model.